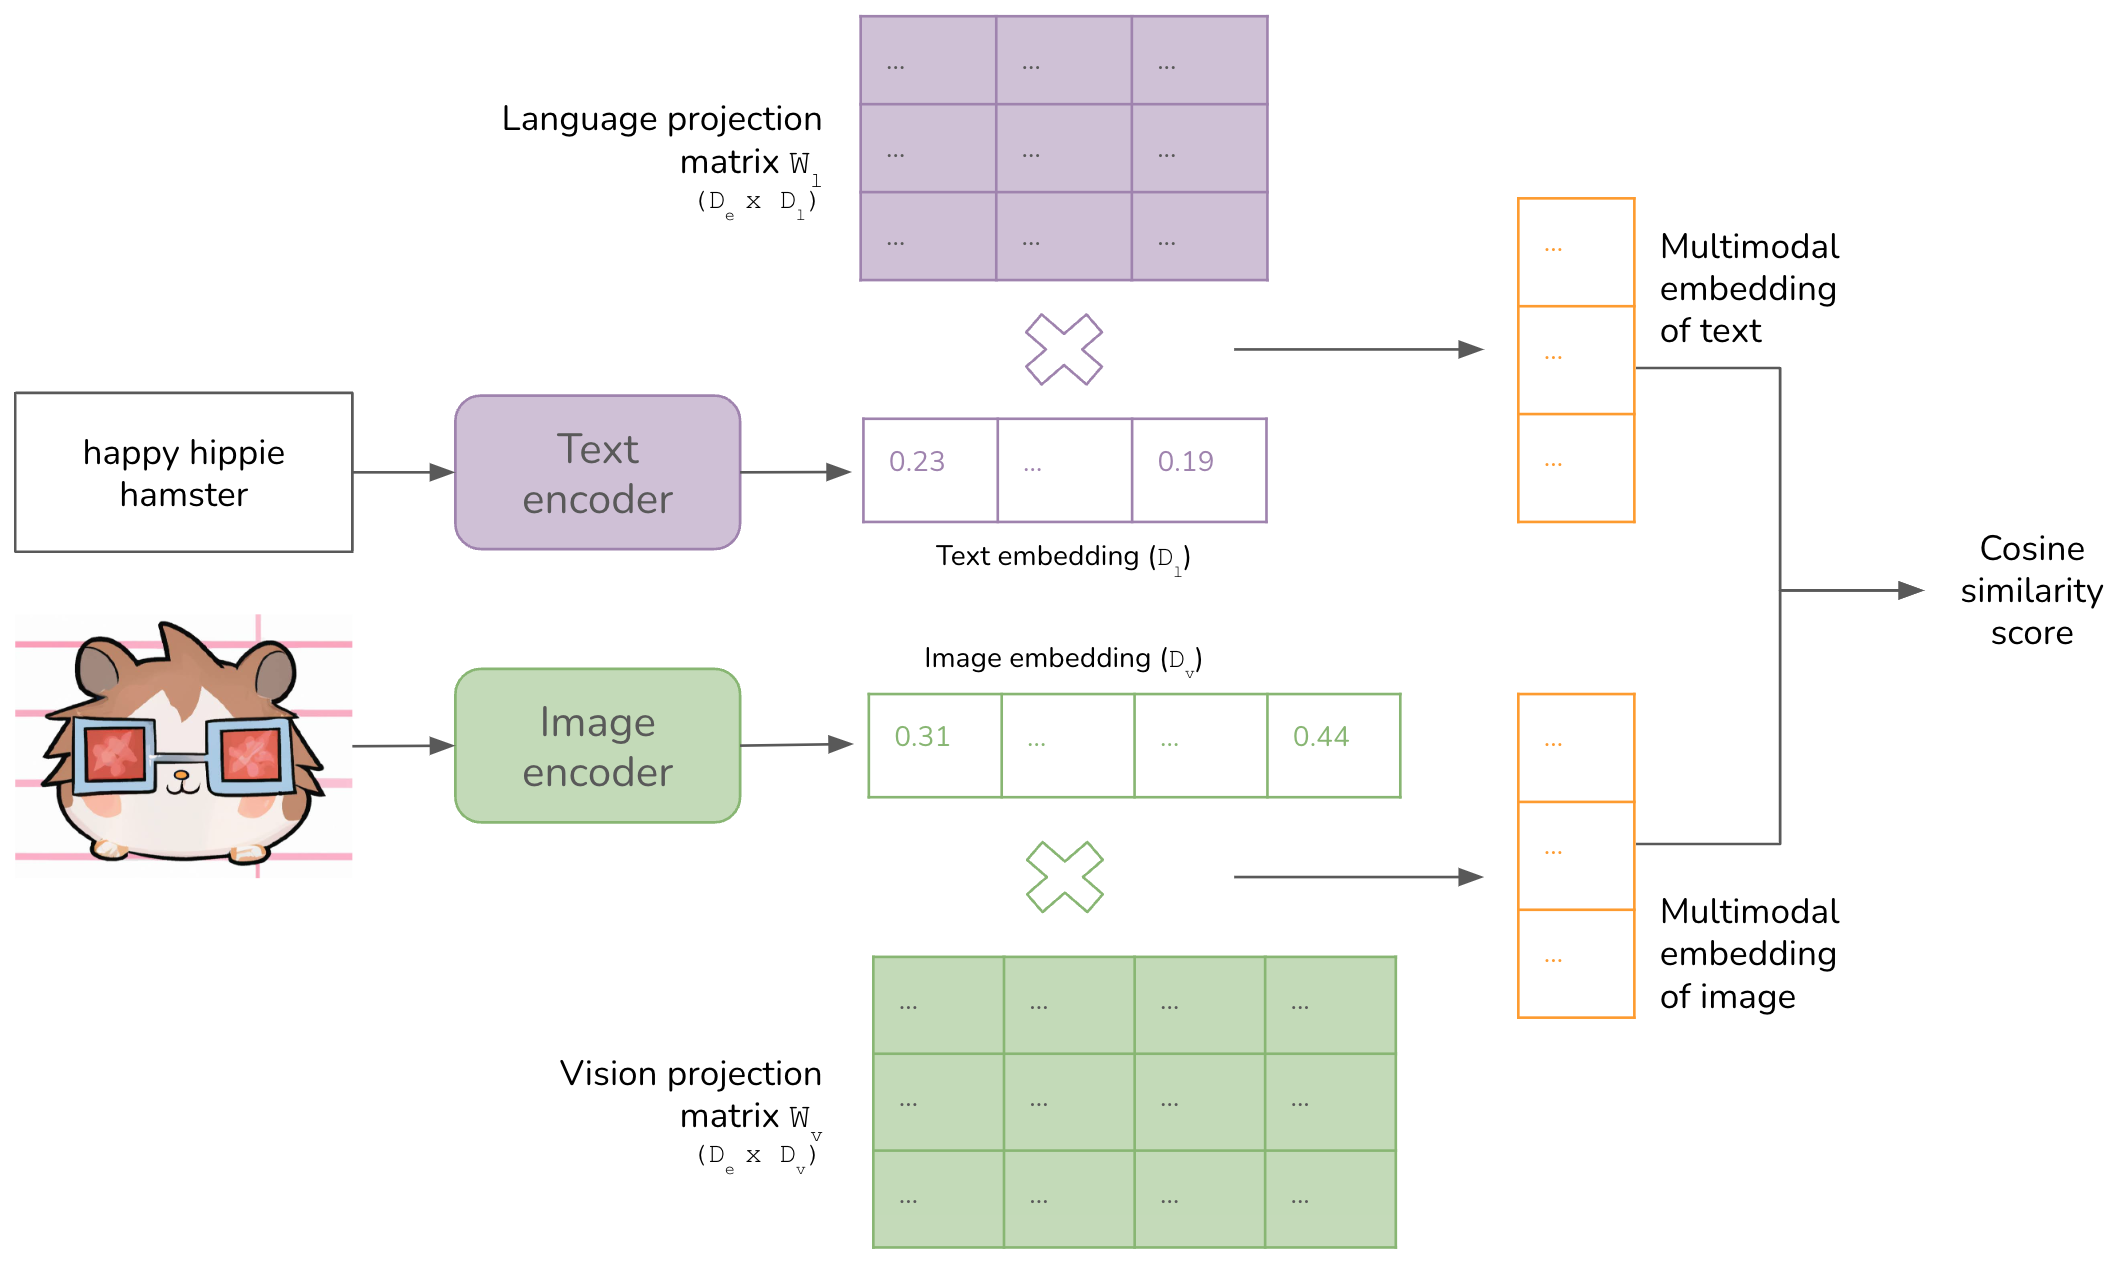
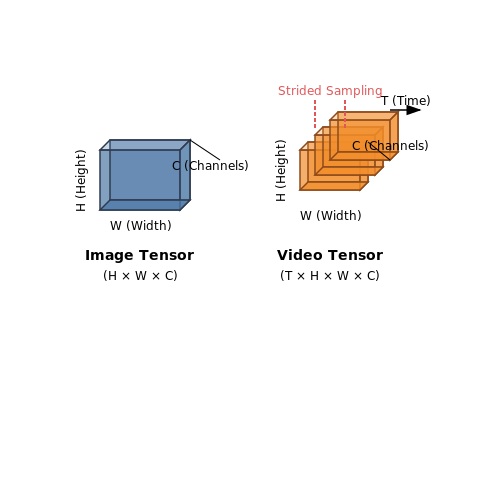
Video Language Model
Document reality with our stunning Video Language Model collection of hundreds of authentic images. honestly portraying photography, images, and pictures. designed to preserve authentic moments and stories. The Video Language Model collection maintains consistent quality standards across all images. Suitable for various applications including web design, social media, personal projects, and digital content creation All Video Language Model images are available in high resolution with professional-grade quality, optimized for both digital and print applications, and include comprehensive metadata for easy organization and usage. Our Video Language Model gallery offers diverse visual resources to bring your ideas to life. Comprehensive tagging systems facilitate quick discovery of relevant Video Language Model content. Each image in our Video Language Model gallery undergoes rigorous quality assessment before inclusion. Diverse style options within the Video Language Model collection suit various aesthetic preferences. The Video Language Model collection represents years of careful curation and professional standards. Whether for commercial projects or personal use, our Video Language Model collection delivers consistent excellence. Our Video Language Model database continuously expands with fresh, relevant content from skilled photographers. Reliable customer support ensures smooth experience throughout the Video Language Model selection process. Cost-effective licensing makes professional Video Language Model photography accessible to all budgets.
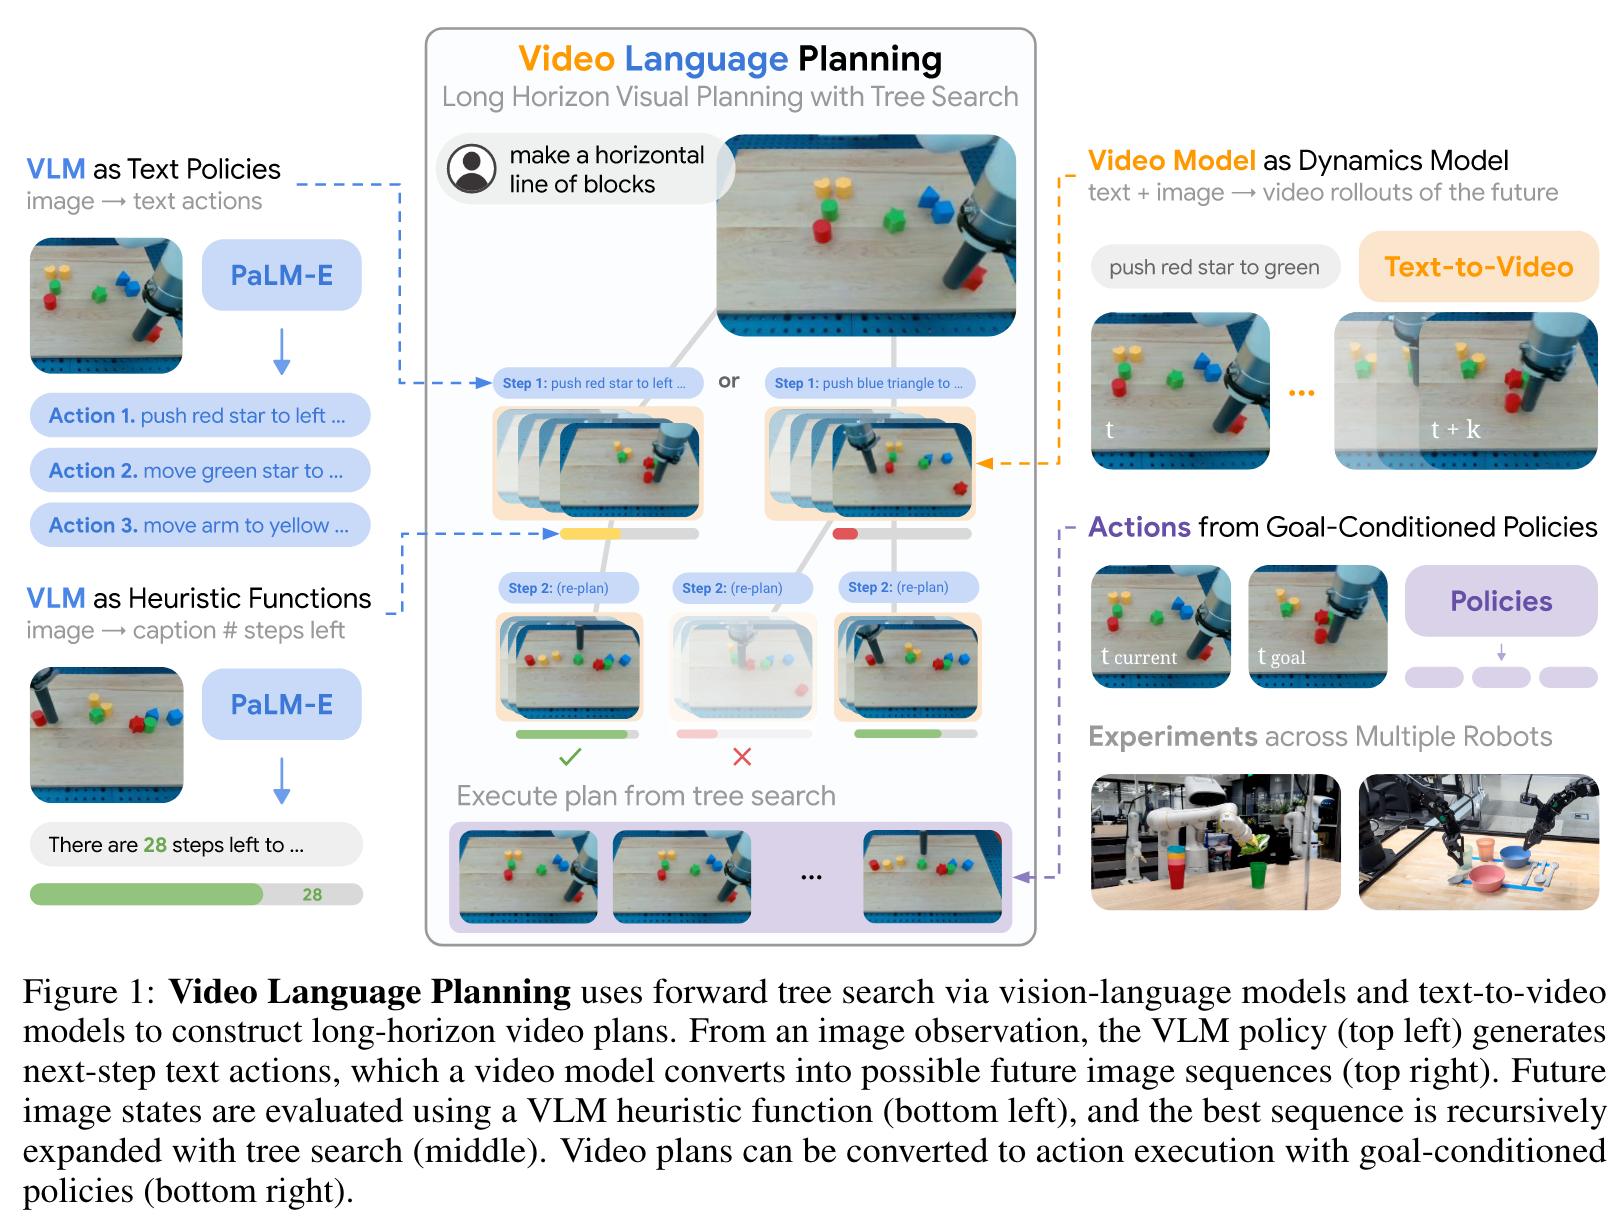
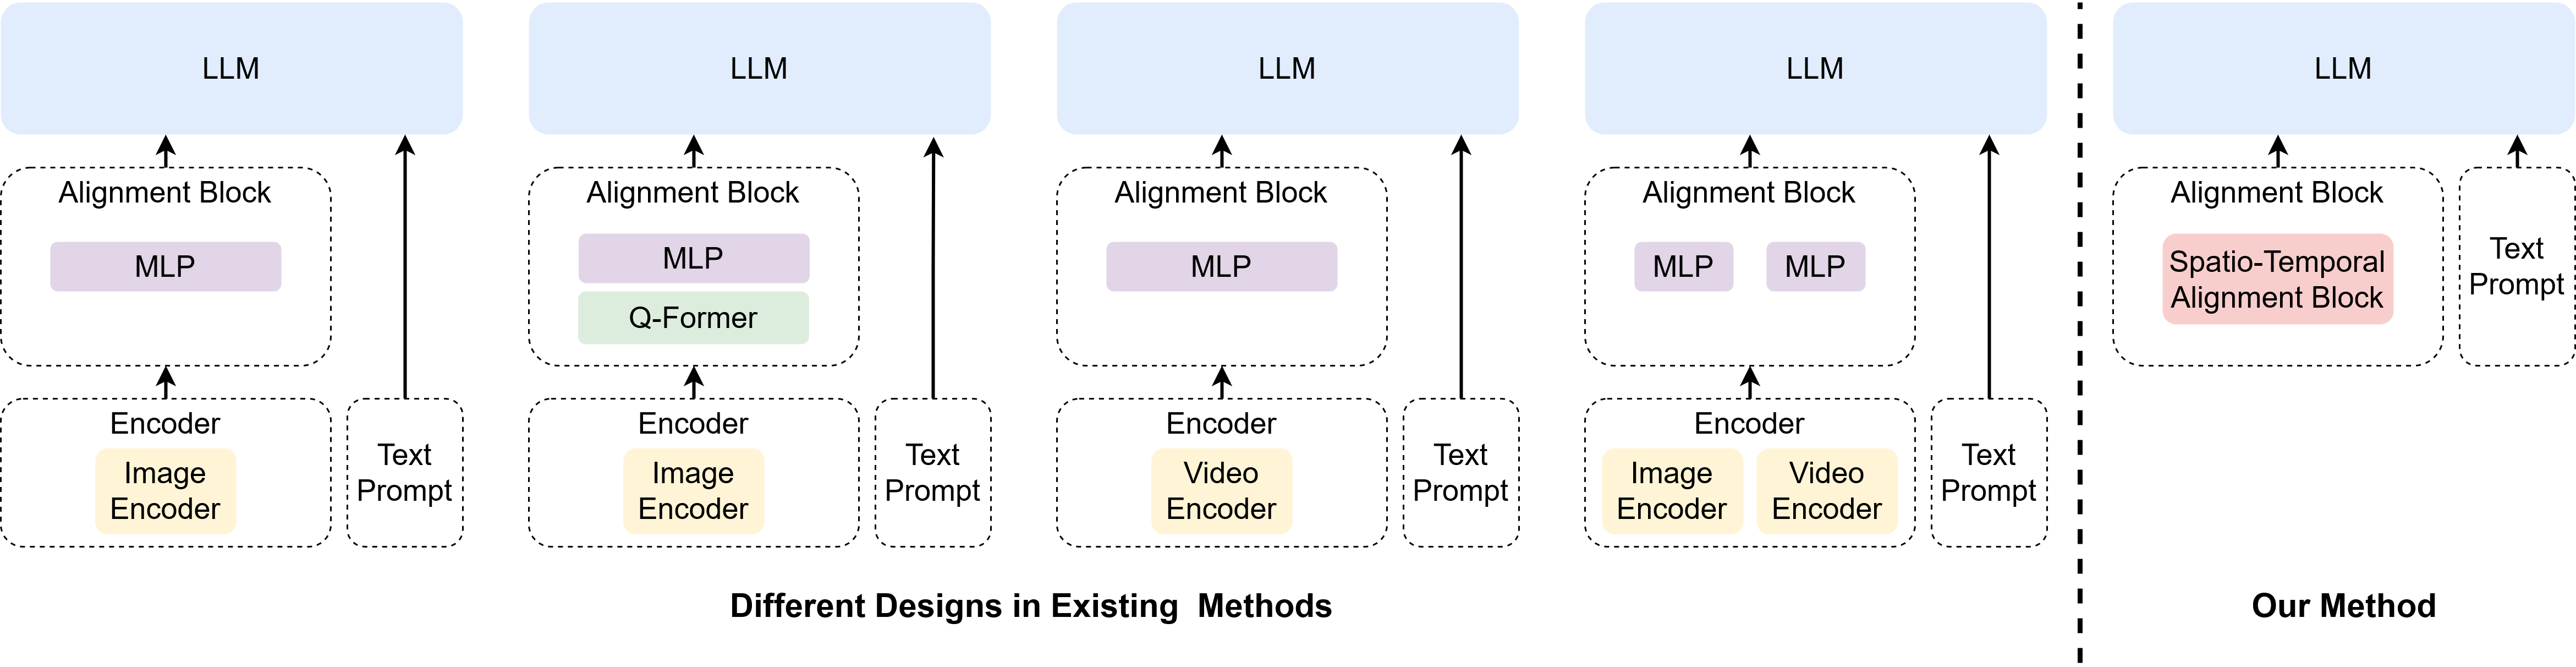
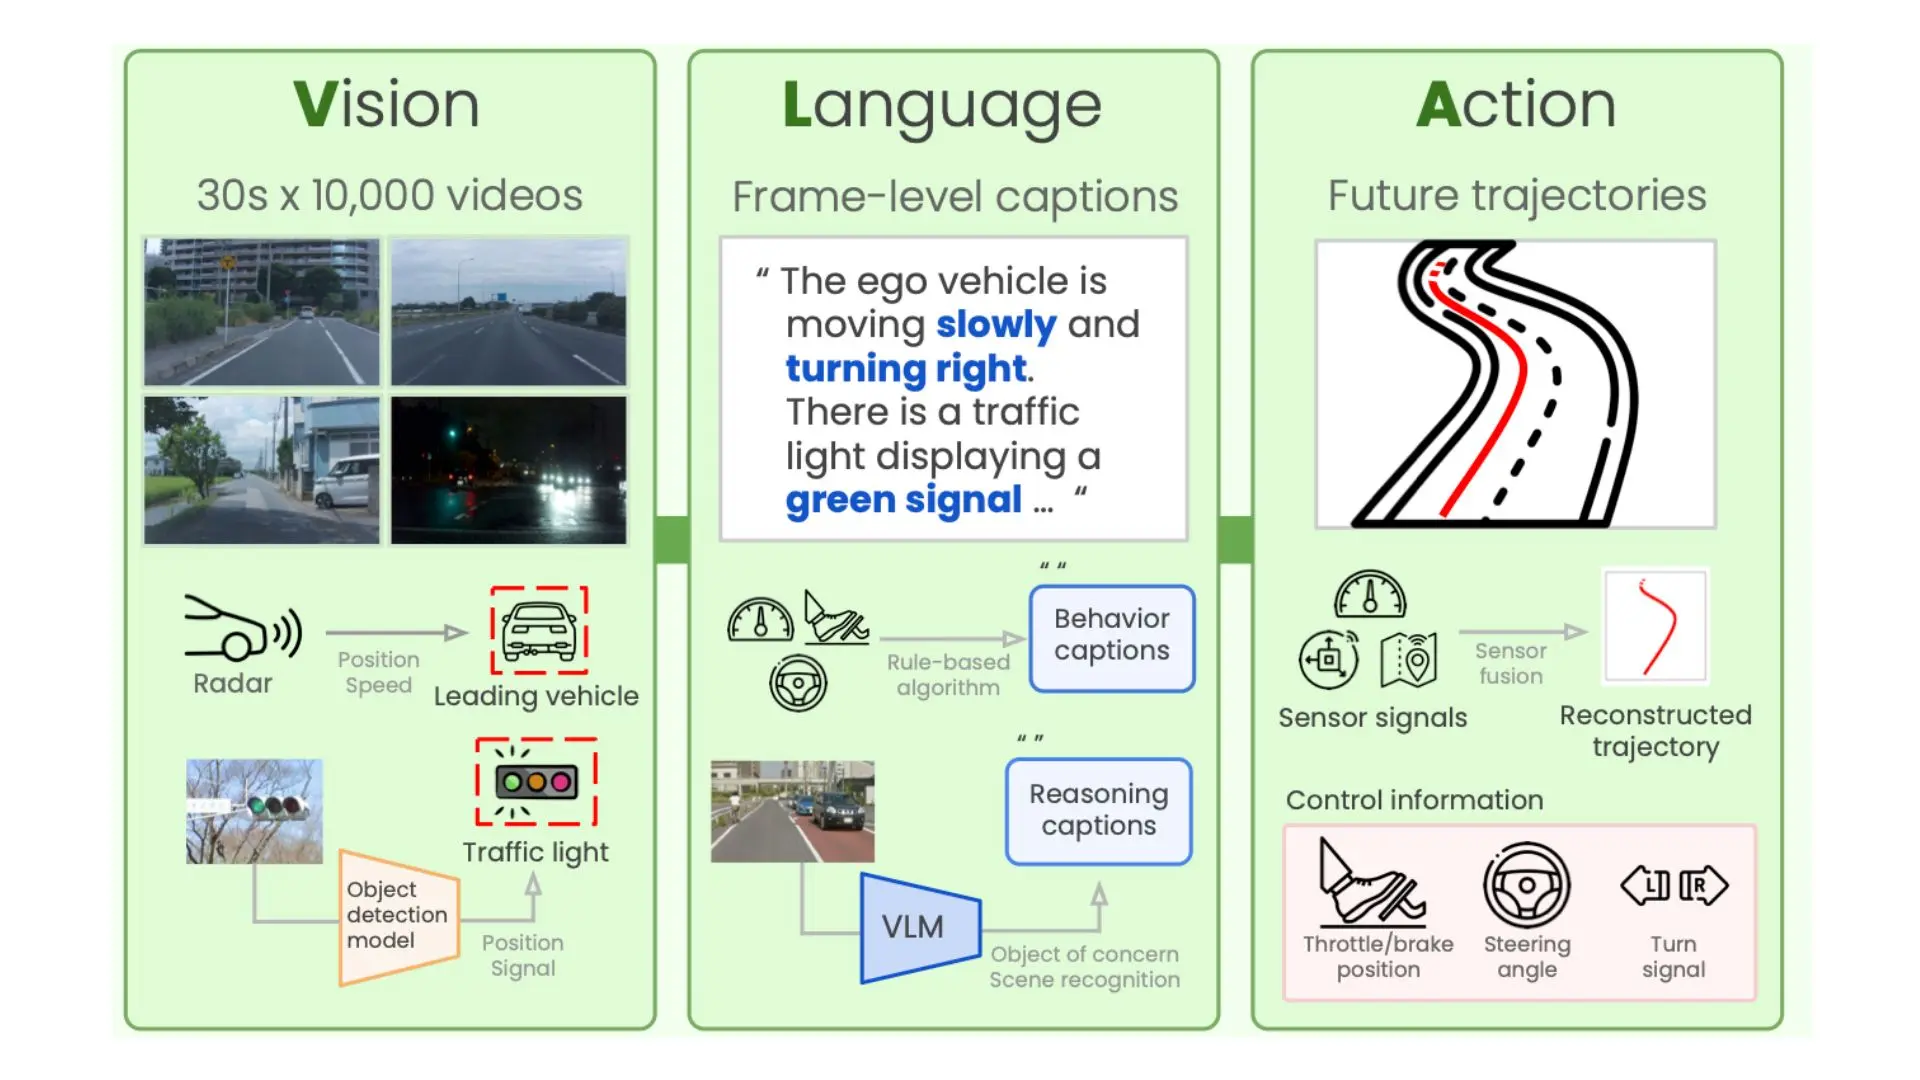
![Video Language Model [논문 리뷰] HiLight: Technical Report on the Motern AI Video Language Model](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/hilight-technical-report-on-the-motern-ai-video-language-model-2.png)


![Video Language Model [2305.13292] VideoLLM: Modeling Video Sequence with Large Language Models](https://ar5iv.labs.arxiv.org/html/2305.13292/assets/imgs/intro_cg.png)
![Video Language Model [2305.13292] VideoLLM: Modeling Video Sequence with Large Language Models](https://ar5iv.labs.arxiv.org/html/2305.13292/assets/imgs/framework.png)


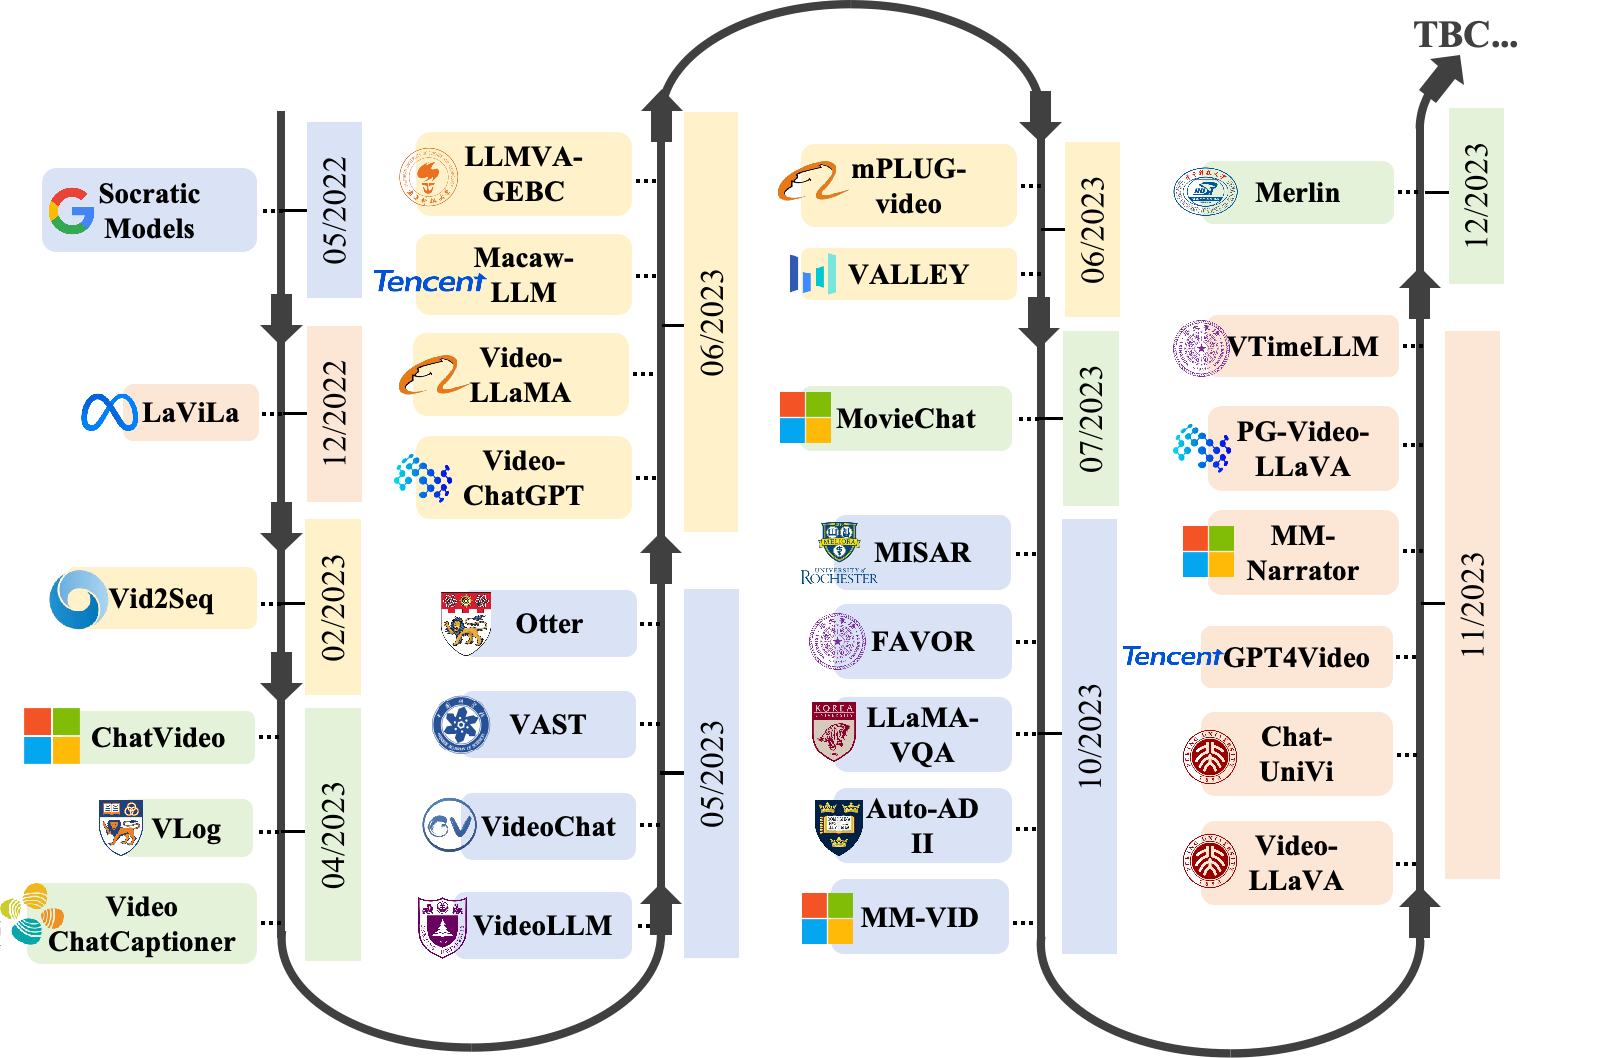
![Video Language Model [2312.17432] Video Understanding with Large Language Models: A Survey](https://ar5iv.labs.arxiv.org/html/2312.17432/assets/figures/timeline.png)


![Video Language Model [论文评述] Bridging Vision Language Models and Symbolic Grounding for Video ...](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/bridging-vision-language-models-and-symbolic-grounding-for-video-question-answering-3.png)
![Video Language Model [논문 리뷰] Empowering Agentic Video Analytics Systems with Video Language ...](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/empowering-agentic-video-analytics-systems-with-video-language-models-3.png)


![Video Language Model [논문 리뷰] ProfVLM: A Lightweight Video-Language Model for Multi-View ...](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/profvlm-a-lightweight-video-language-model-for-multi-view-proficiency-estimation-0.png)


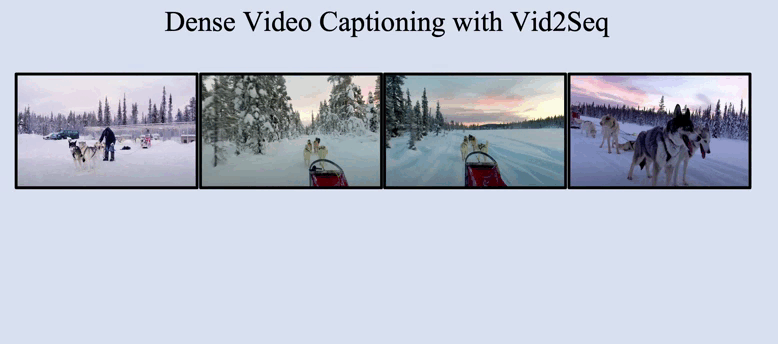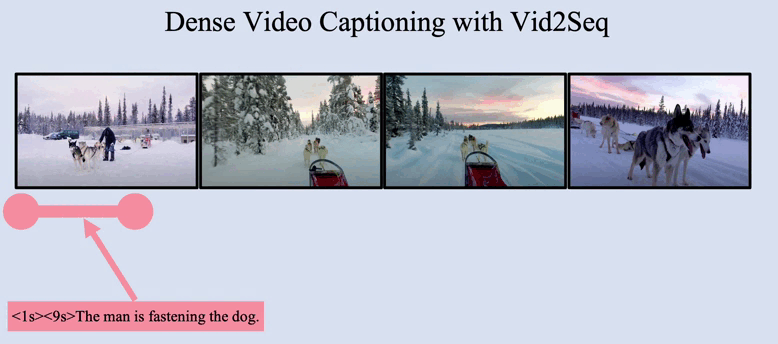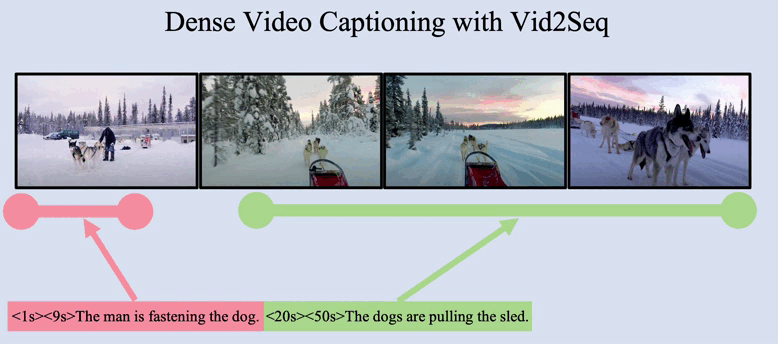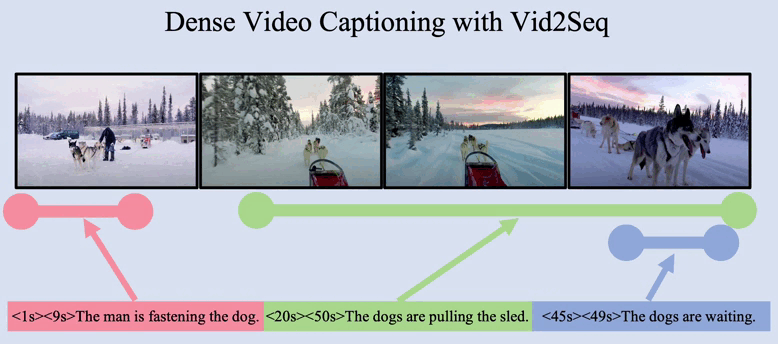
![Video Language Model [2302.14115] Vid2Seq: Large-Scale Pretraining of a Visual Language ...](https://ar5iv.labs.arxiv.org/html/2302.14115/assets/x6.png)


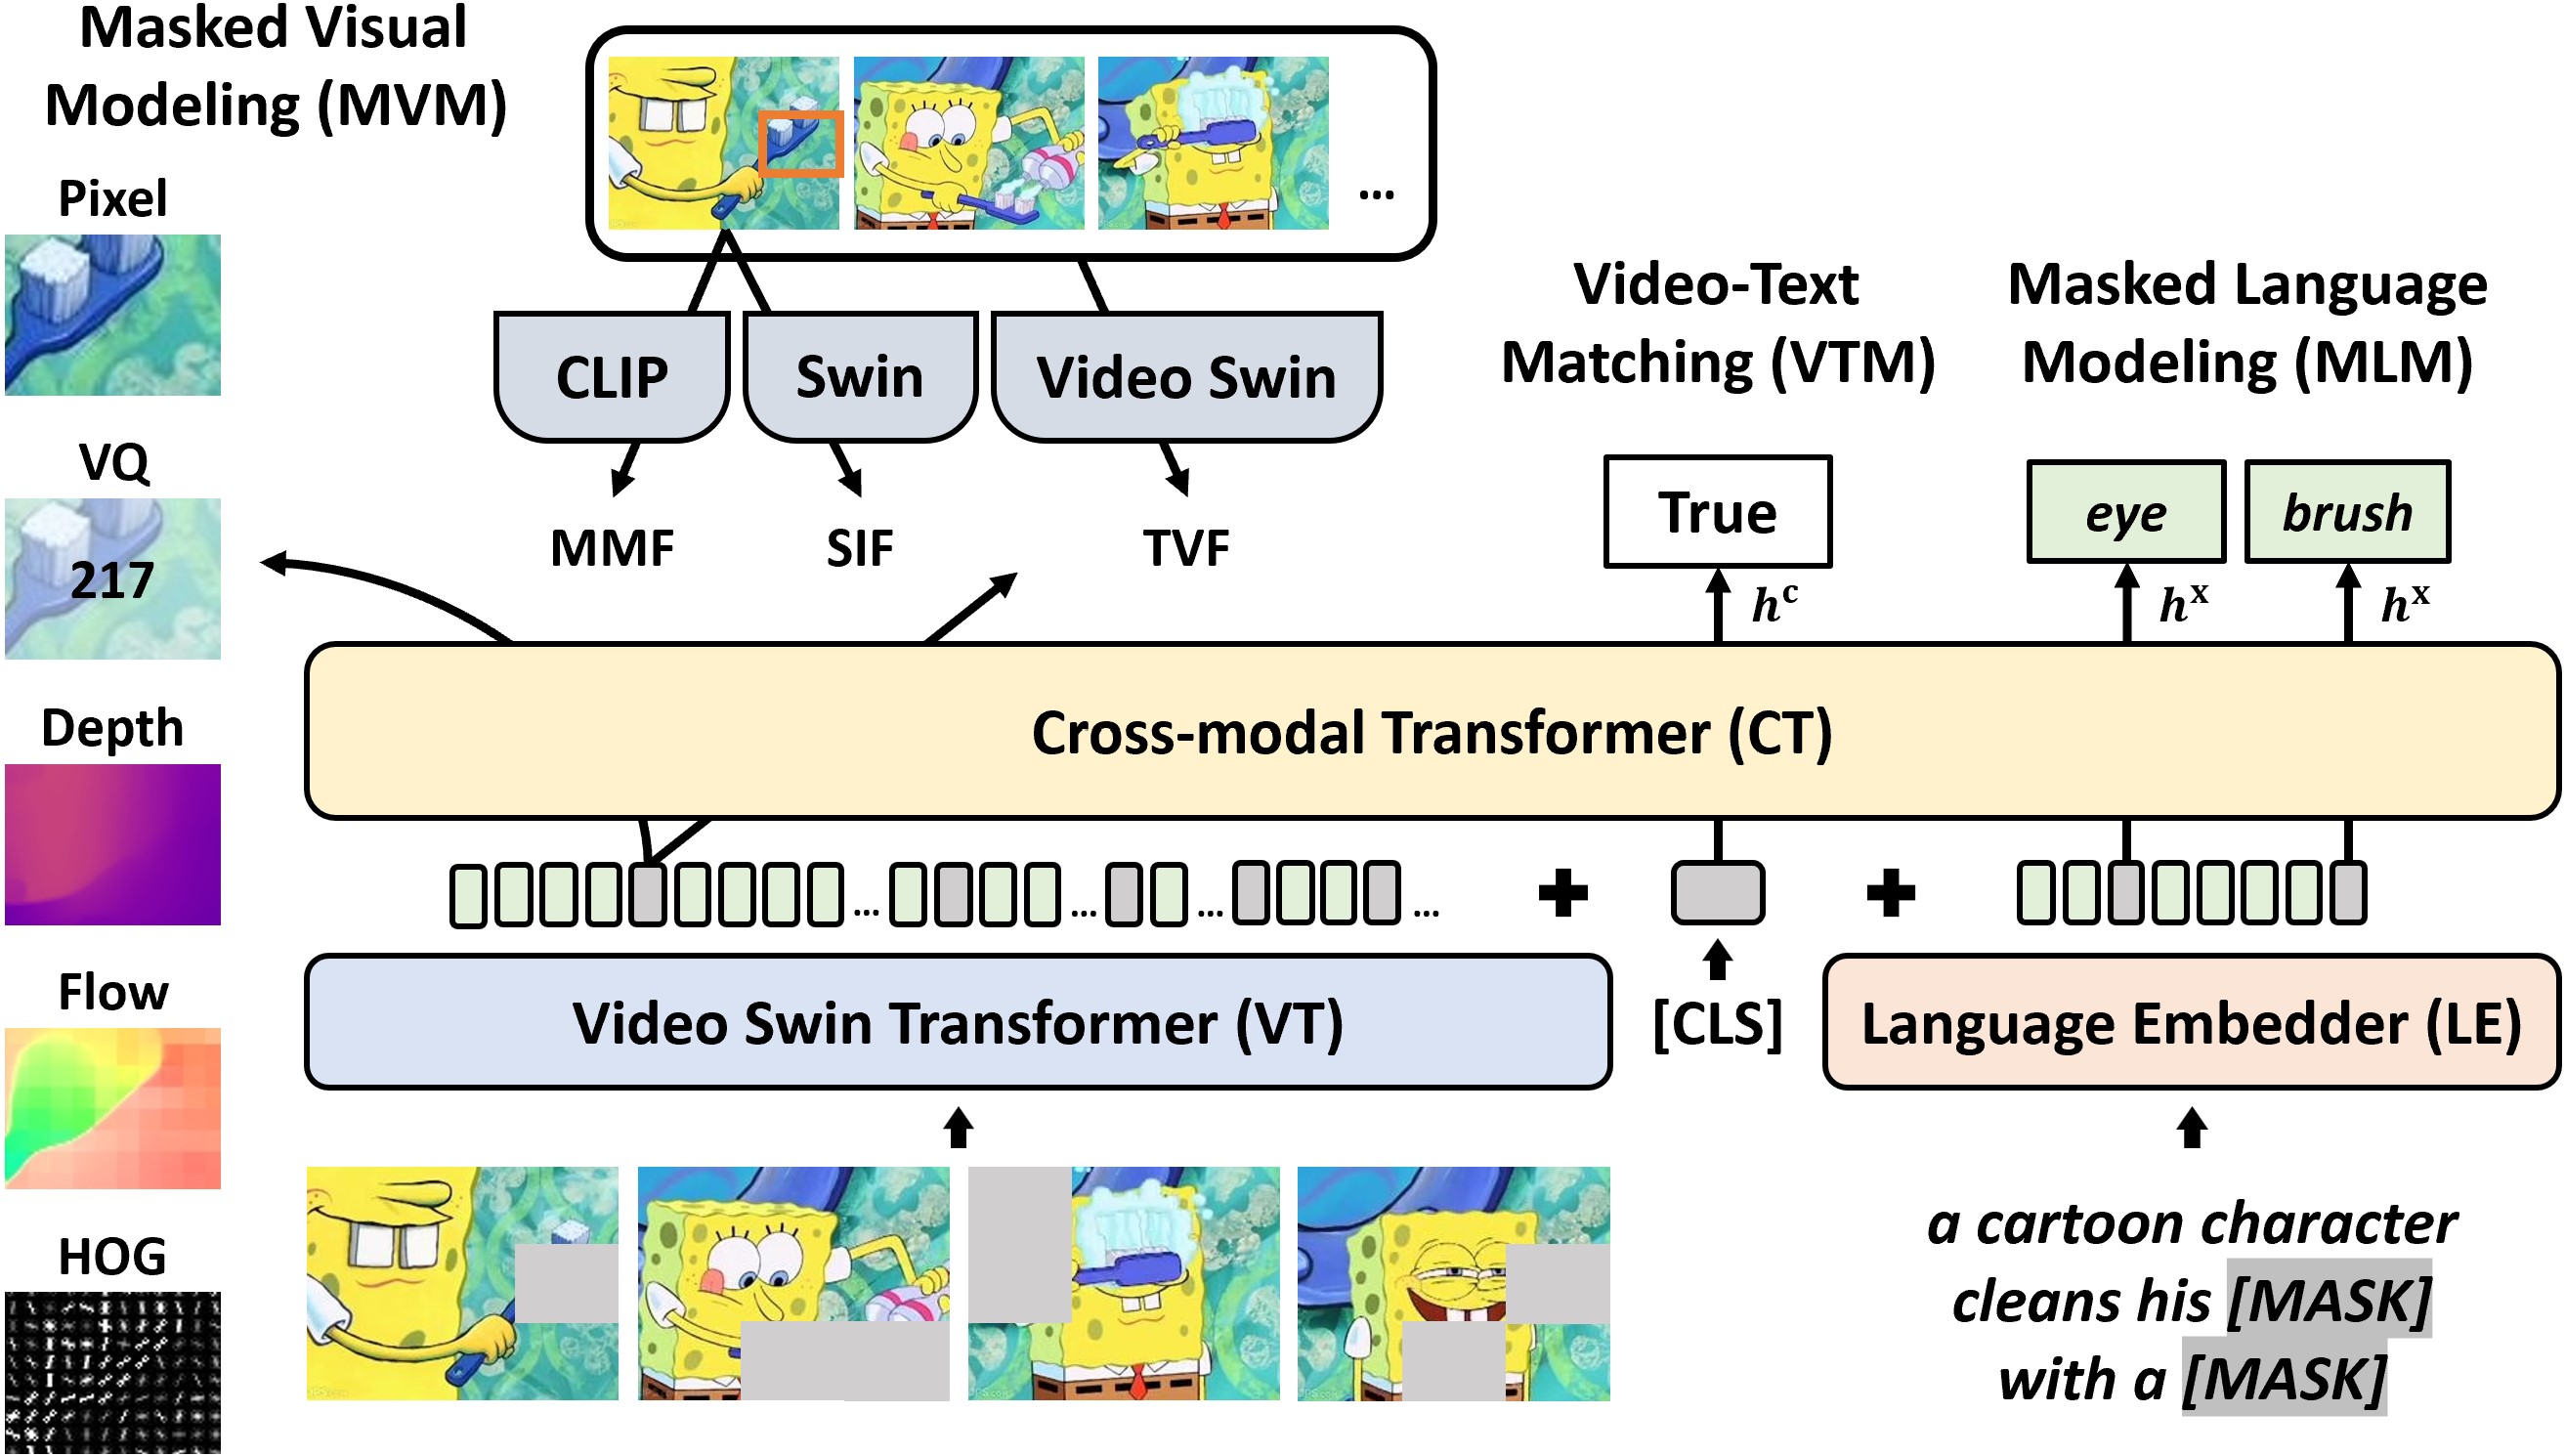
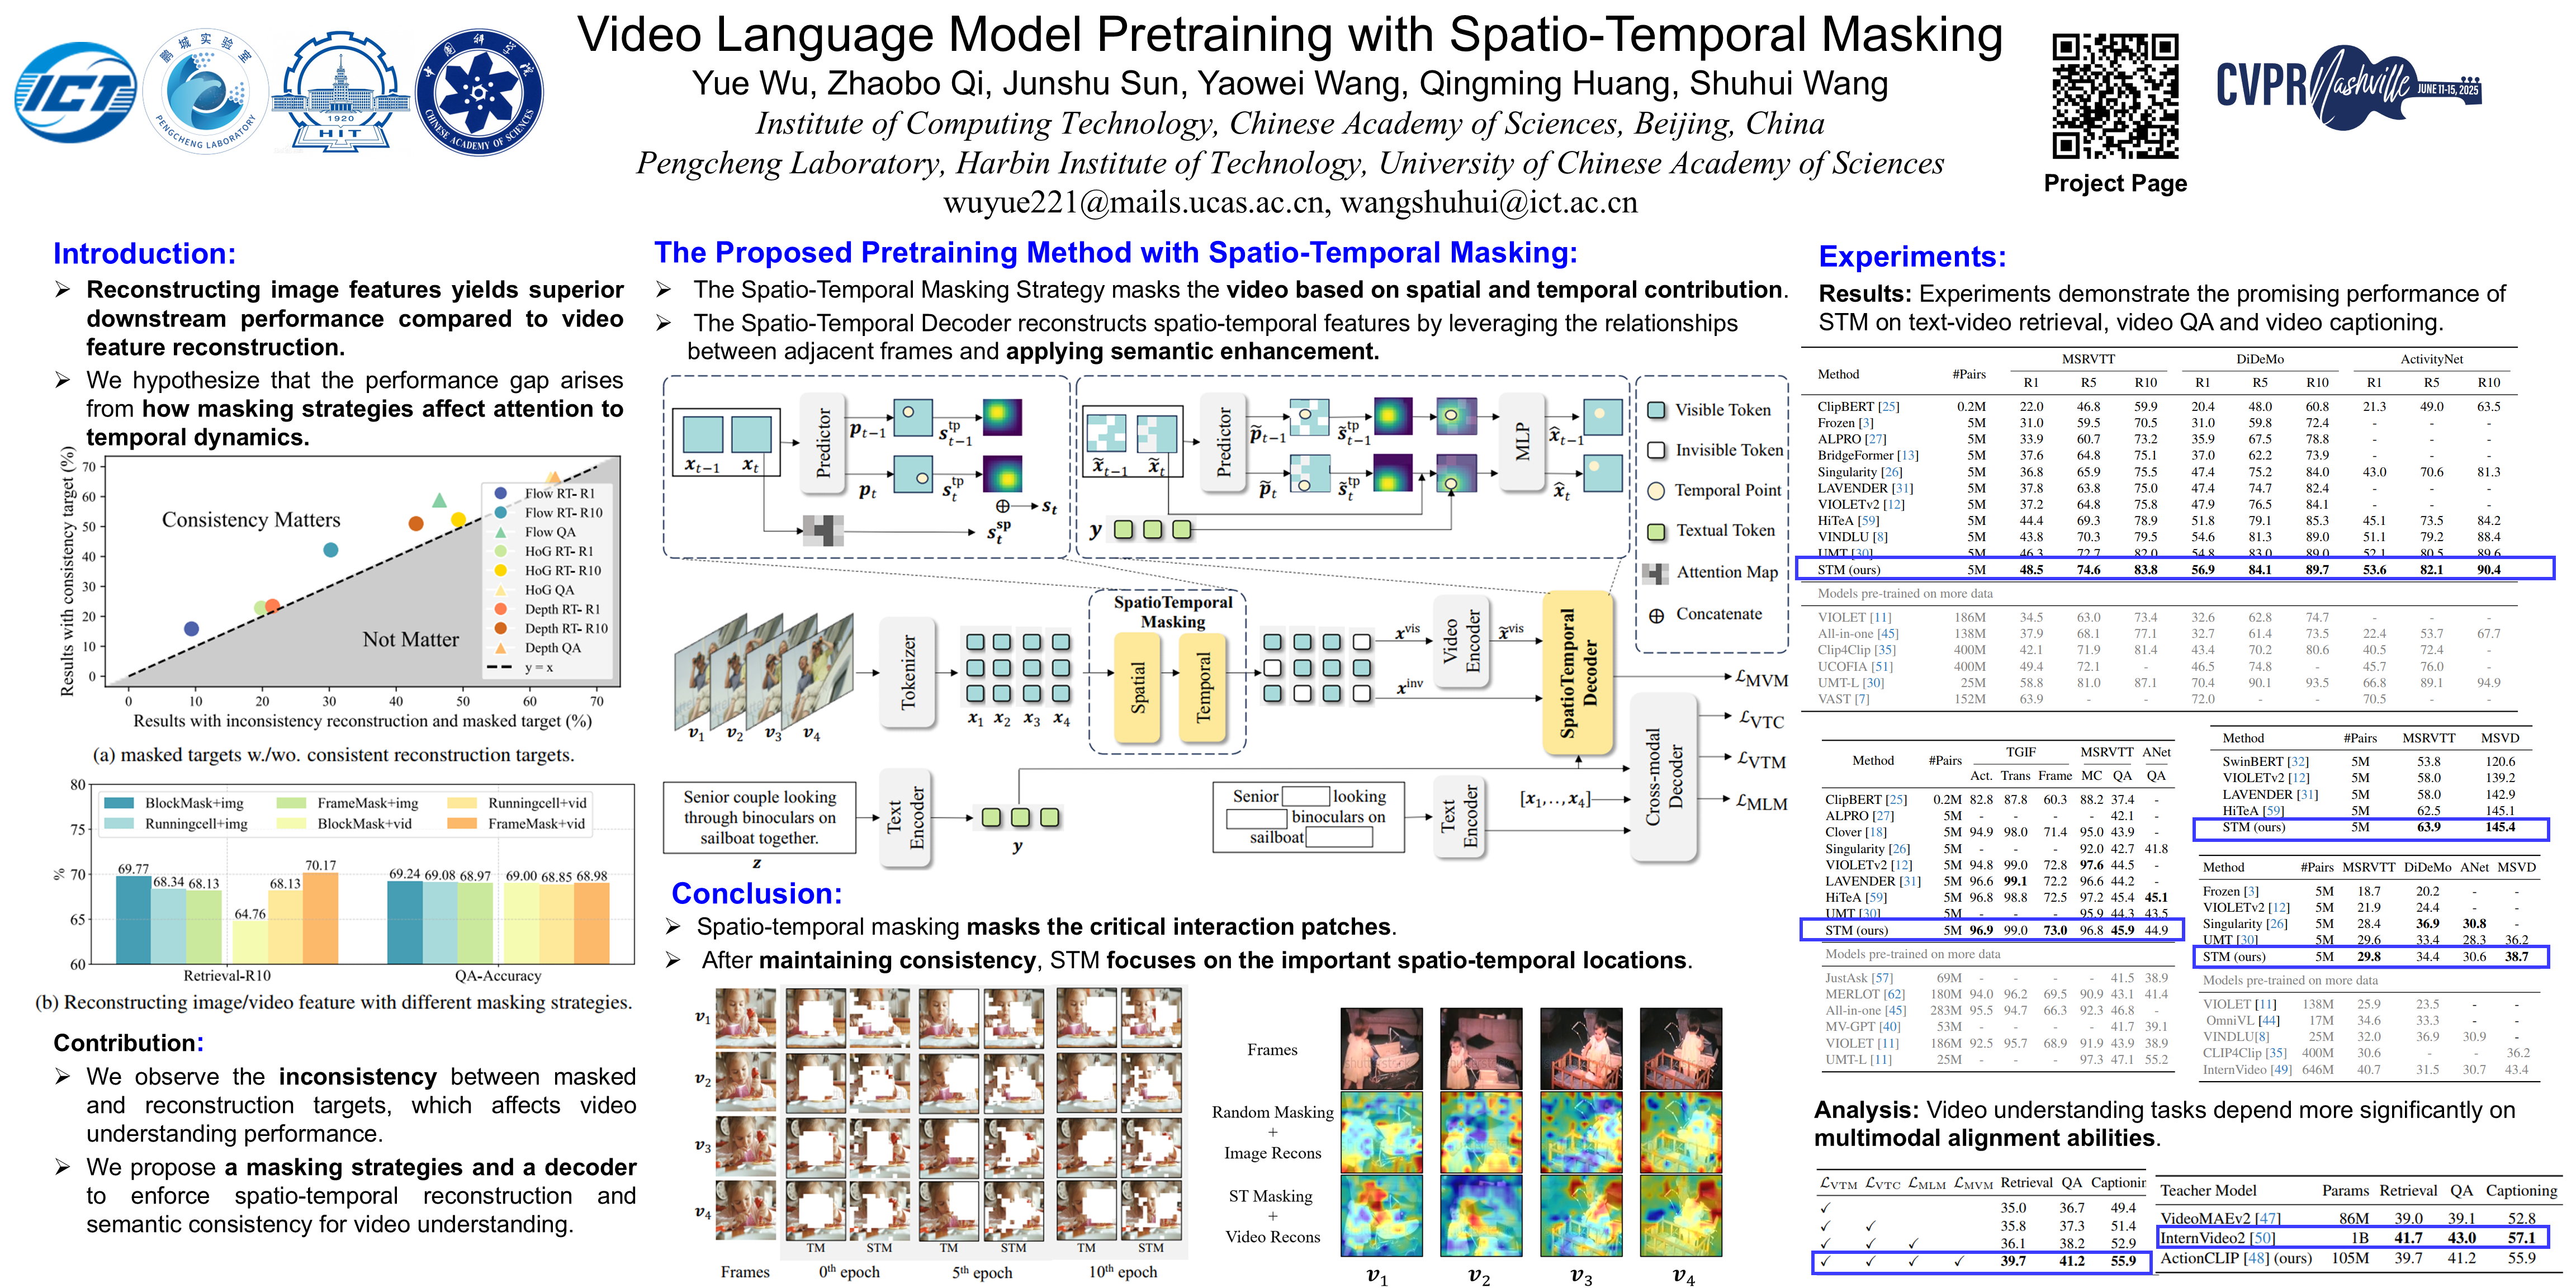
![Video Language Model [논문 리뷰] VLM: 복잡한 건 싫다! 마스킹 하나로 끝내는 비디오-언어 모델 Task-agnostic Video ...](https://blog.kakaocdn.net/dna/Vrkoo/dJMcafSzfkH/AAAAAAAAAAAAAAAAAAAAANxn6L3eZiHj43Qclr6-_VE1d6n4TfLz6d8NOTCzjApi/img.png?credential=yqXZFxpELC7KVnFOS48ylbz2pIh7yKj8&expires=1767193199&allow_ip=&allow_referer=&signature=kVtIUhSmzmrogu%2FGU45pGD6V0p8%3D)
![Video Language Model [2404.03384] LongVLM: Efficient Long Video Understanding via Large ...](https://ar5iv.labs.arxiv.org/html/2404.03384/assets/x2.png)
![Video Language Model [2302.14115] Vid2Seq: Large-Scale Pretraining of a Visual Language ...](https://ar5iv.labs.arxiv.org/html/2302.14115/assets/x2.png)


![Video Language Model [论文评述] HENASY: Learning to Assemble Scene-Entities for Egocentric Video ...](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/henasy-learning-to-assemble-scene-entities-for-egocentric-video-language-model-1.png)

![Video Language Model [2403.10517] VideoAgent: Long-form Video Understanding with Large ...](https://ar5iv.labs.arxiv.org/html/2403.10517/assets/x3.png)


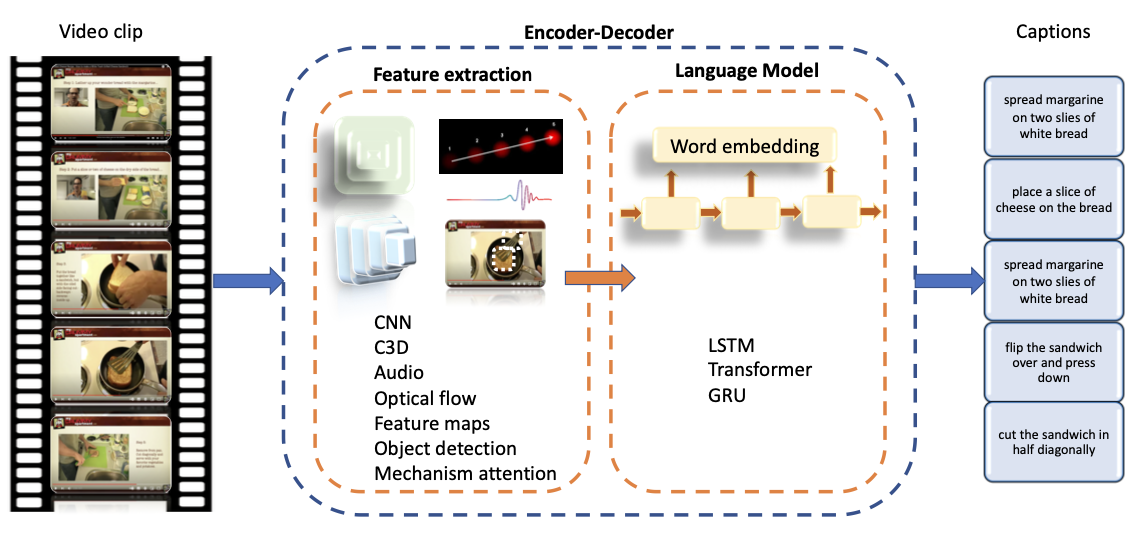
![Video Language Model [2209.01540] An Empirical Study of End-to-End Video-Language ...](https://ar5iv.labs.arxiv.org/html/2209.01540/assets/figs/fig_intro3.jpg)

![Video Language Model [2206.01720] Revisiting the “Video” in Video-Language Understanding](https://ar5iv.labs.arxiv.org/html/2206.01720/assets/figures/fig1.png)


![Video Language Model Open AI API Key Setup with ChatGPT, Codex & DALLE [2025]](https://dextralabs.com/wp-content/uploads/2025/08/vlm-models-1024x576.webp)


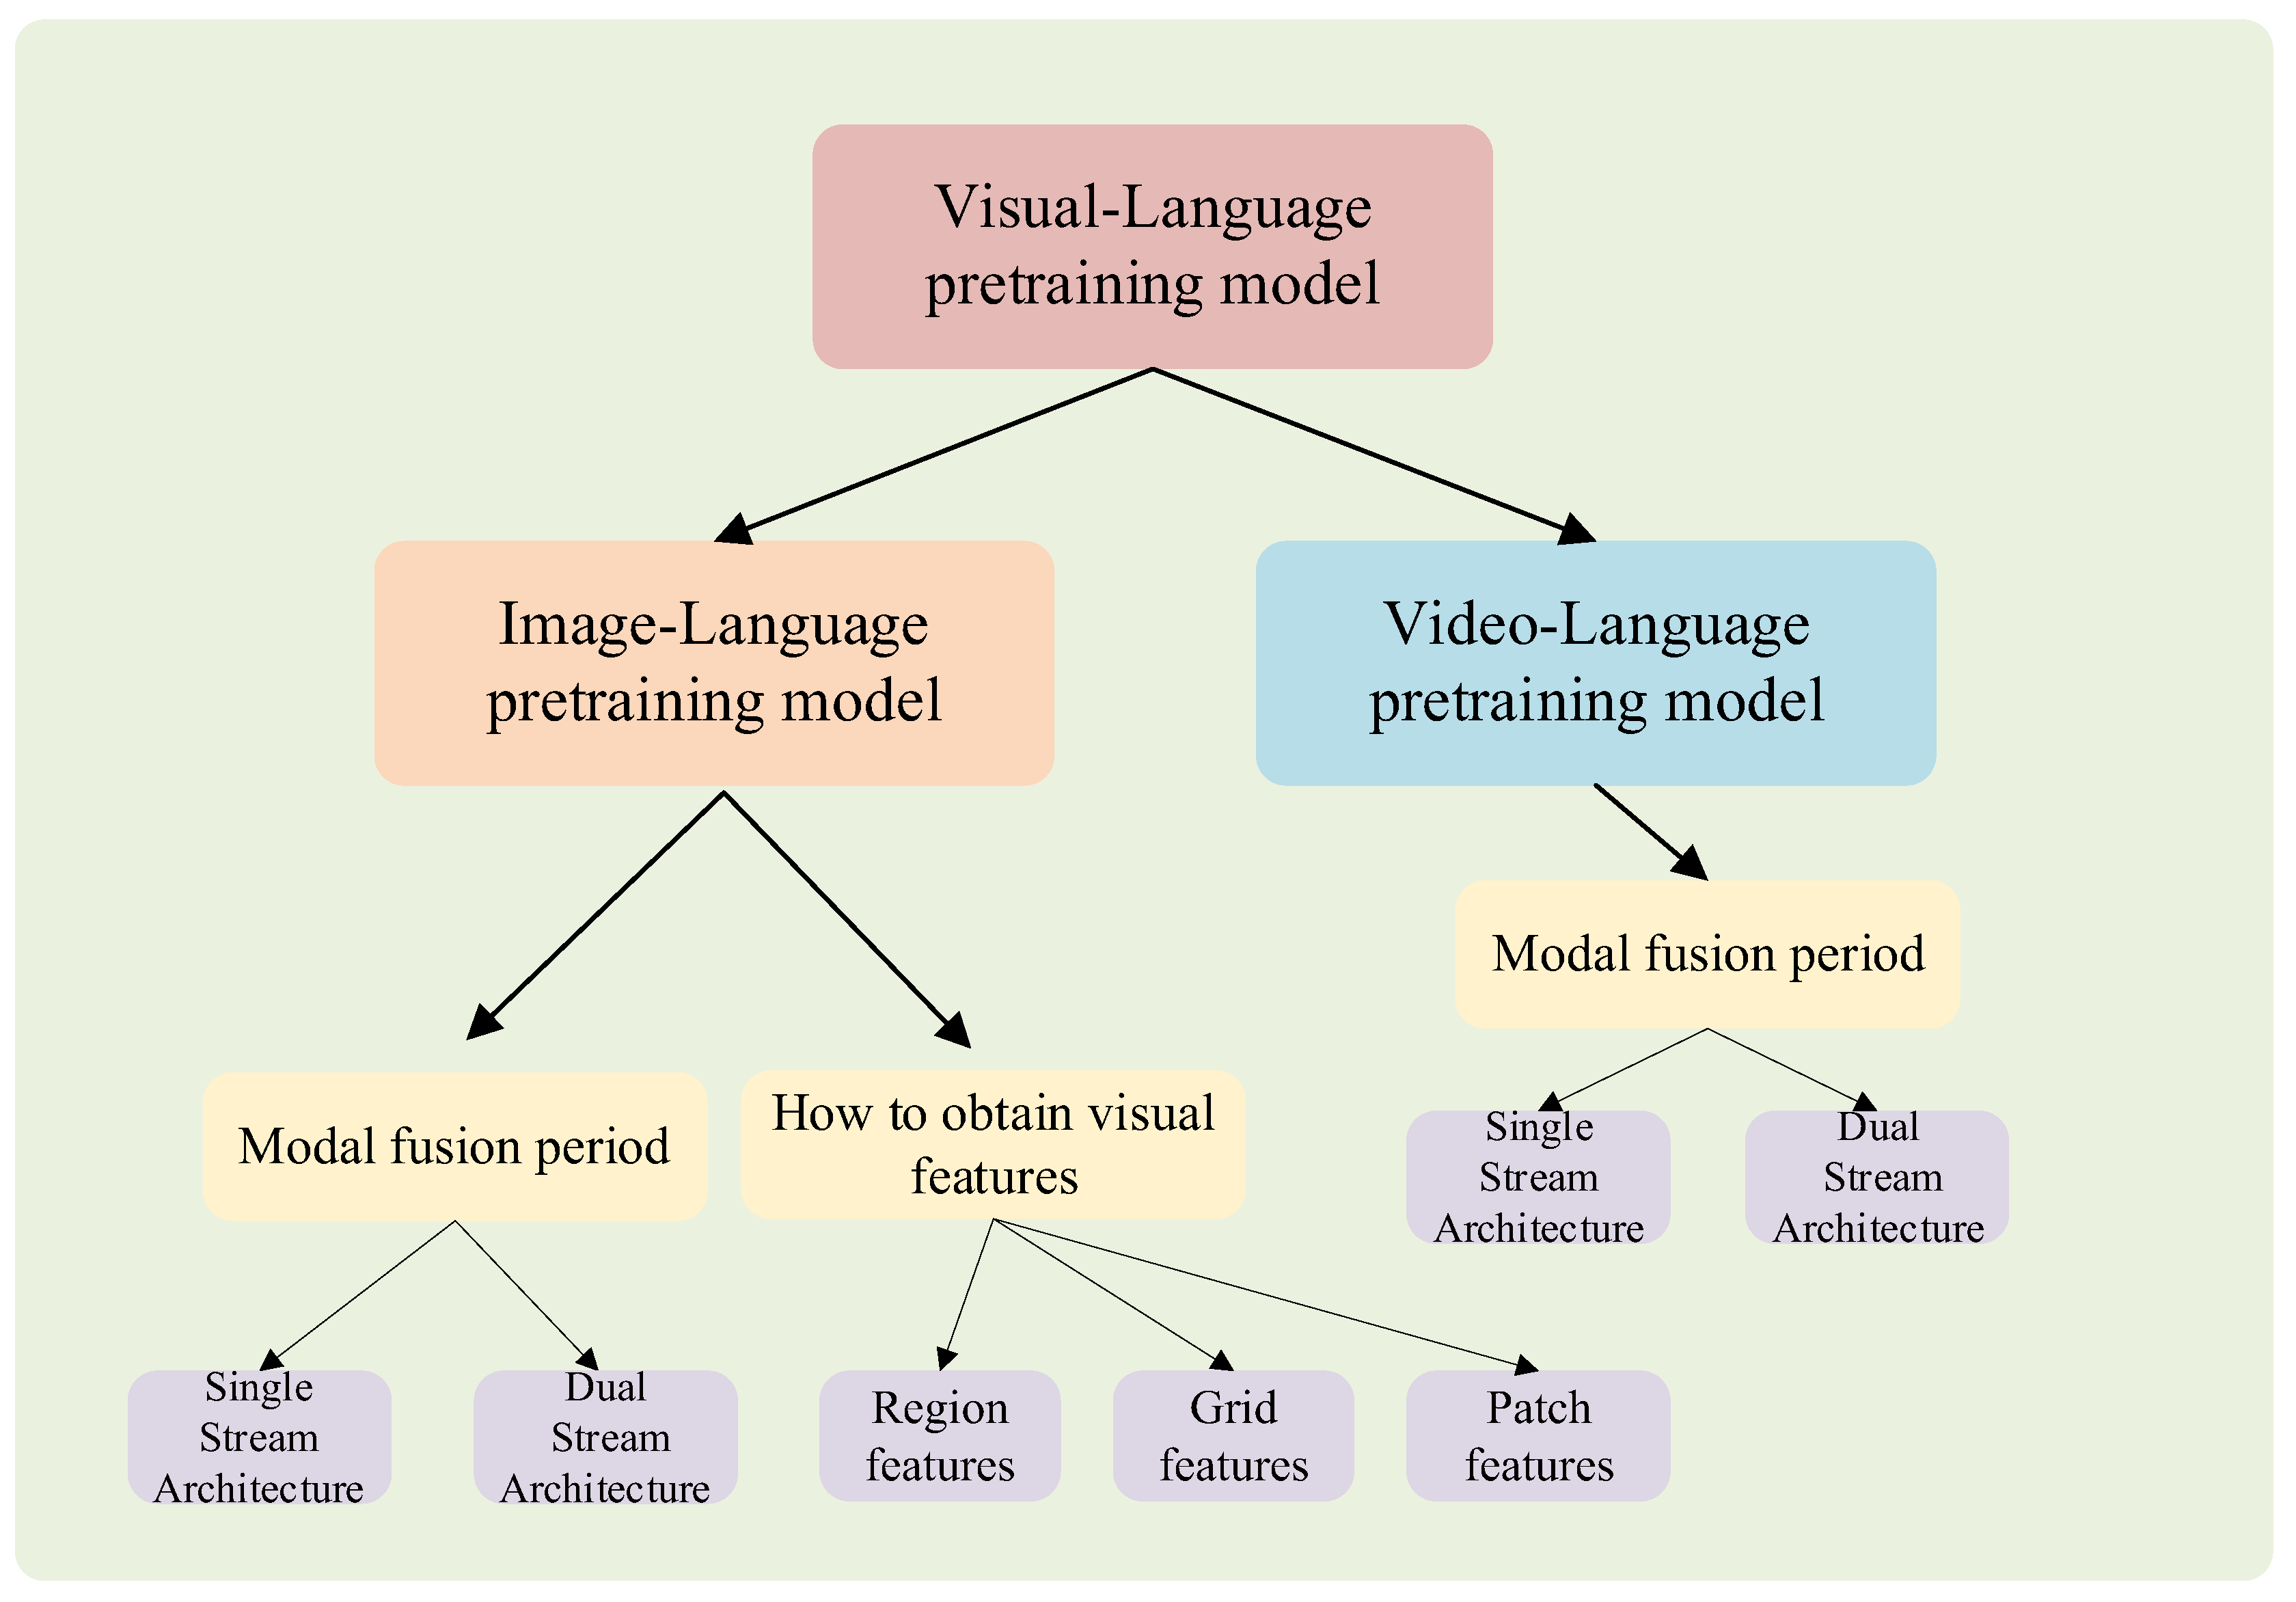
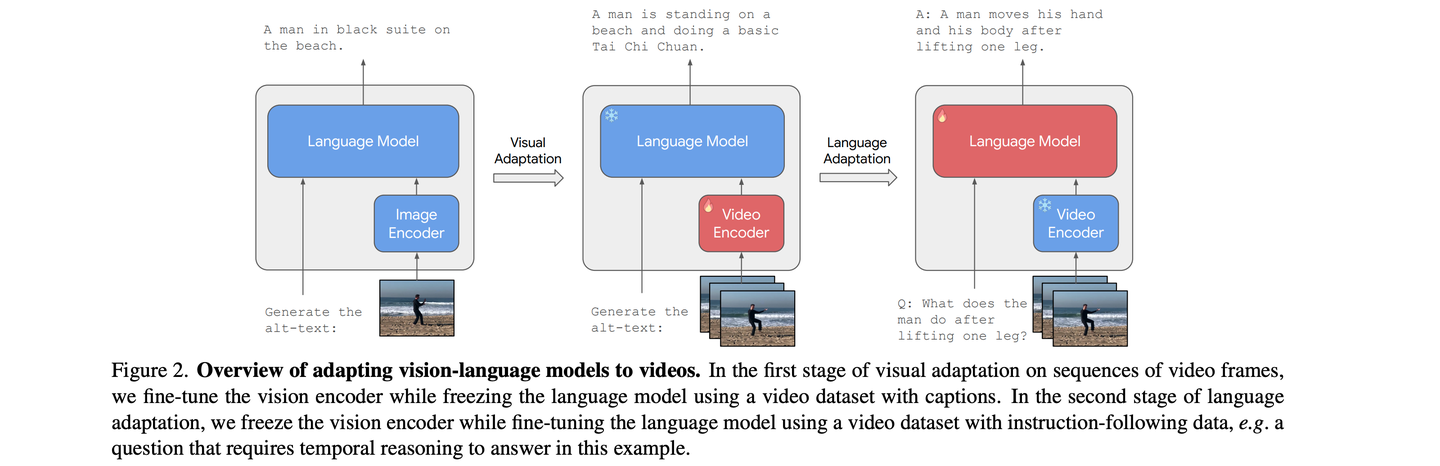
![Video Language Model [논문 리뷰] Image-to-Video Transfer Learning based on Image-Language ...](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/image-to-video-transfer-learning-based-on-image-language-foundation-models-a-comprehensive-survey-0.png)