Clip Multimodal Model
Innovate the future with our stunning technology Clip Multimodal Model collection of comprehensive galleries of cutting-edge images. innovatively presenting photography, images, and pictures. ideal for innovation showcases and presentations. Each Clip Multimodal Model image is carefully selected for superior visual impact and professional quality. Suitable for various applications including web design, social media, personal projects, and digital content creation All Clip Multimodal Model images are available in high resolution with professional-grade quality, optimized for both digital and print applications, and include comprehensive metadata for easy organization and usage. Our Clip Multimodal Model gallery offers diverse visual resources to bring your ideas to life. Comprehensive tagging systems facilitate quick discovery of relevant Clip Multimodal Model content. Our Clip Multimodal Model database continuously expands with fresh, relevant content from skilled photographers. Diverse style options within the Clip Multimodal Model collection suit various aesthetic preferences. Professional licensing options accommodate both commercial and educational usage requirements. Instant download capabilities enable immediate access to chosen Clip Multimodal Model images. Each image in our Clip Multimodal Model gallery undergoes rigorous quality assessment before inclusion. Cost-effective licensing makes professional Clip Multimodal Model photography accessible to all budgets. Whether for commercial projects or personal use, our Clip Multimodal Model collection delivers consistent excellence.
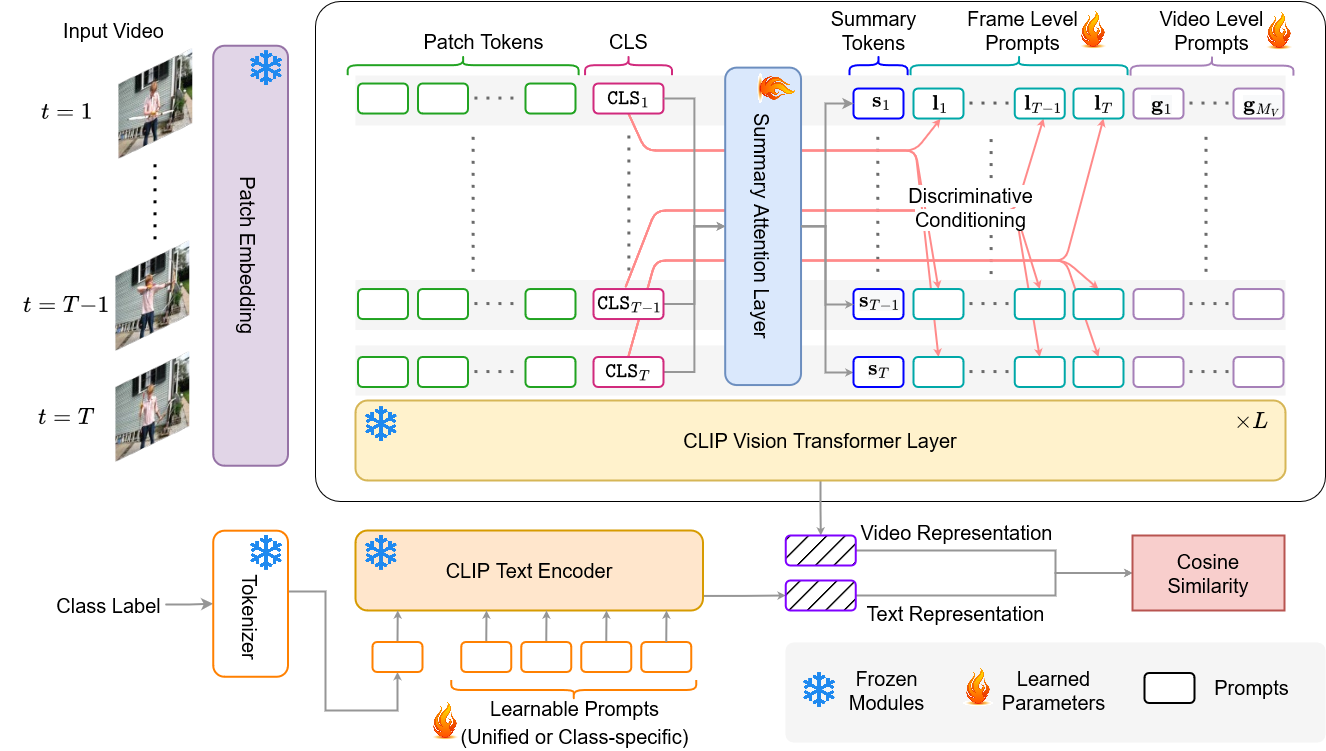


![Clip Multimodal Model [2304.03307] Vita-CLIP: Video and text adaptive CLIP via Multimodal ...](https://ar5iv.labs.arxiv.org/html/2304.03307/assets/figures/main_arch.png)


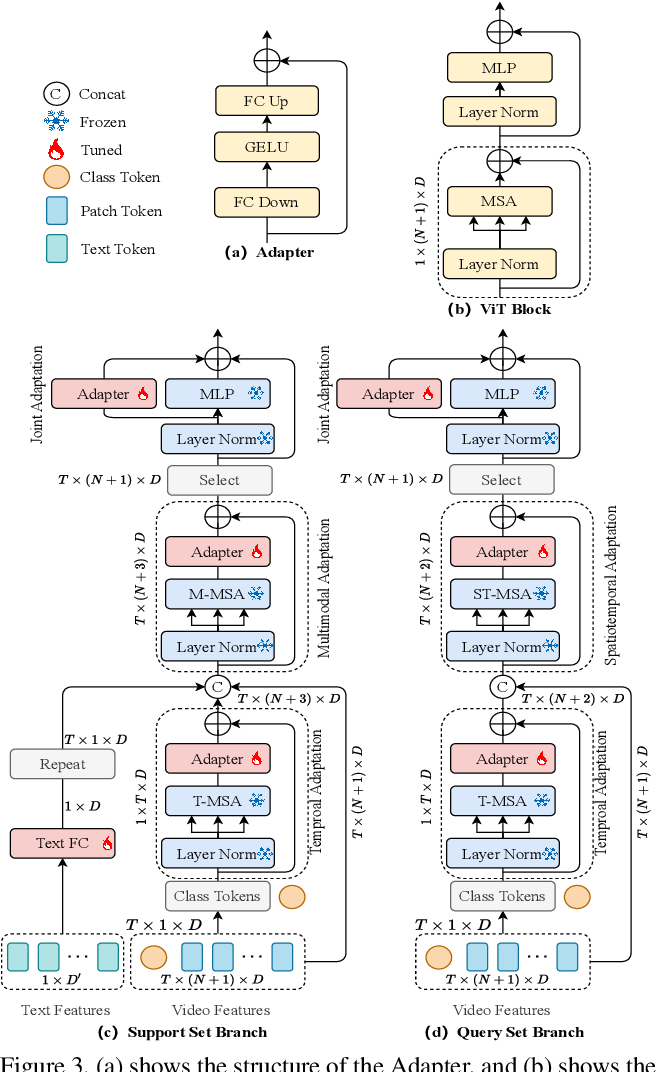
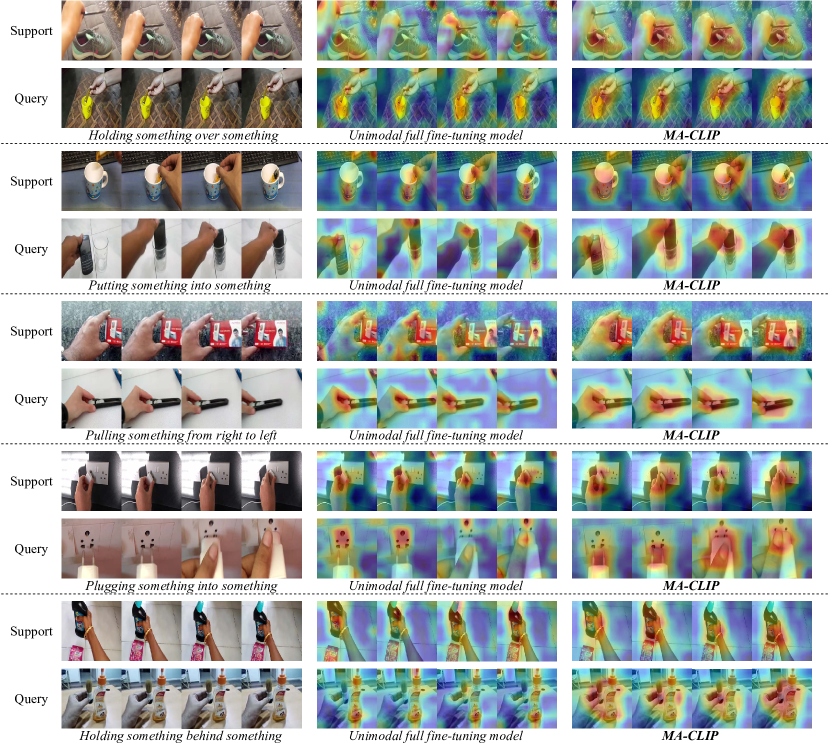
![Clip Multimodal Model [2308.01532] Multimodal Adaptation of CLIP for Few-Shot Action Recognition](https://ar5iv.labs.arxiv.org/html/2308.01532/assets/x5.png)


![Clip Multimodal Model [2203.06386] Enabling Multimodal Generation on CLIP via Vision-Language ...](https://ar5iv.labs.arxiv.org/html/2203.06386/assets/x3.png)
![Clip Multimodal Model [2303.06591] Accommodating Audio Modality in CLIP for Multimodal Processing](https://ar5iv.labs.arxiv.org/html/2303.06591/assets/model_all.png)


![Clip Multimodal Model [2203.06386] Enabling Multimodal Generation on CLIP via Vision-Language ...](https://ar5iv.labs.arxiv.org/html/2203.06386/assets/x2.png)
![Clip Multimodal Model [2406.16141] Multimodal Multilabel Classification by CLIP](https://ar5iv.labs.arxiv.org/html/2406.16141/assets/graph/viltclass.png)


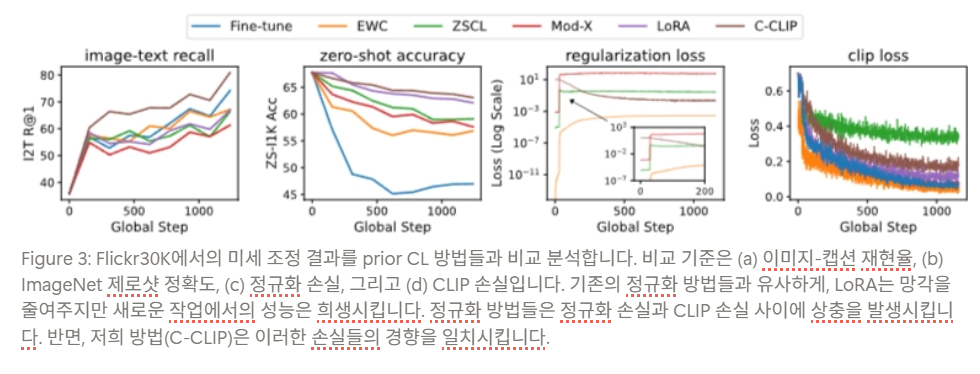
![Clip Multimodal Model [논문 리뷰]C-CLIP: MULTIMODAL CONTINUAL LEARNING FOR VISION-LANGUAGE MODEL](https://velog.velcdn.com/images/wldnd7145/post/833354fc-e593-4229-b798-5d8696dd1295/image.png)


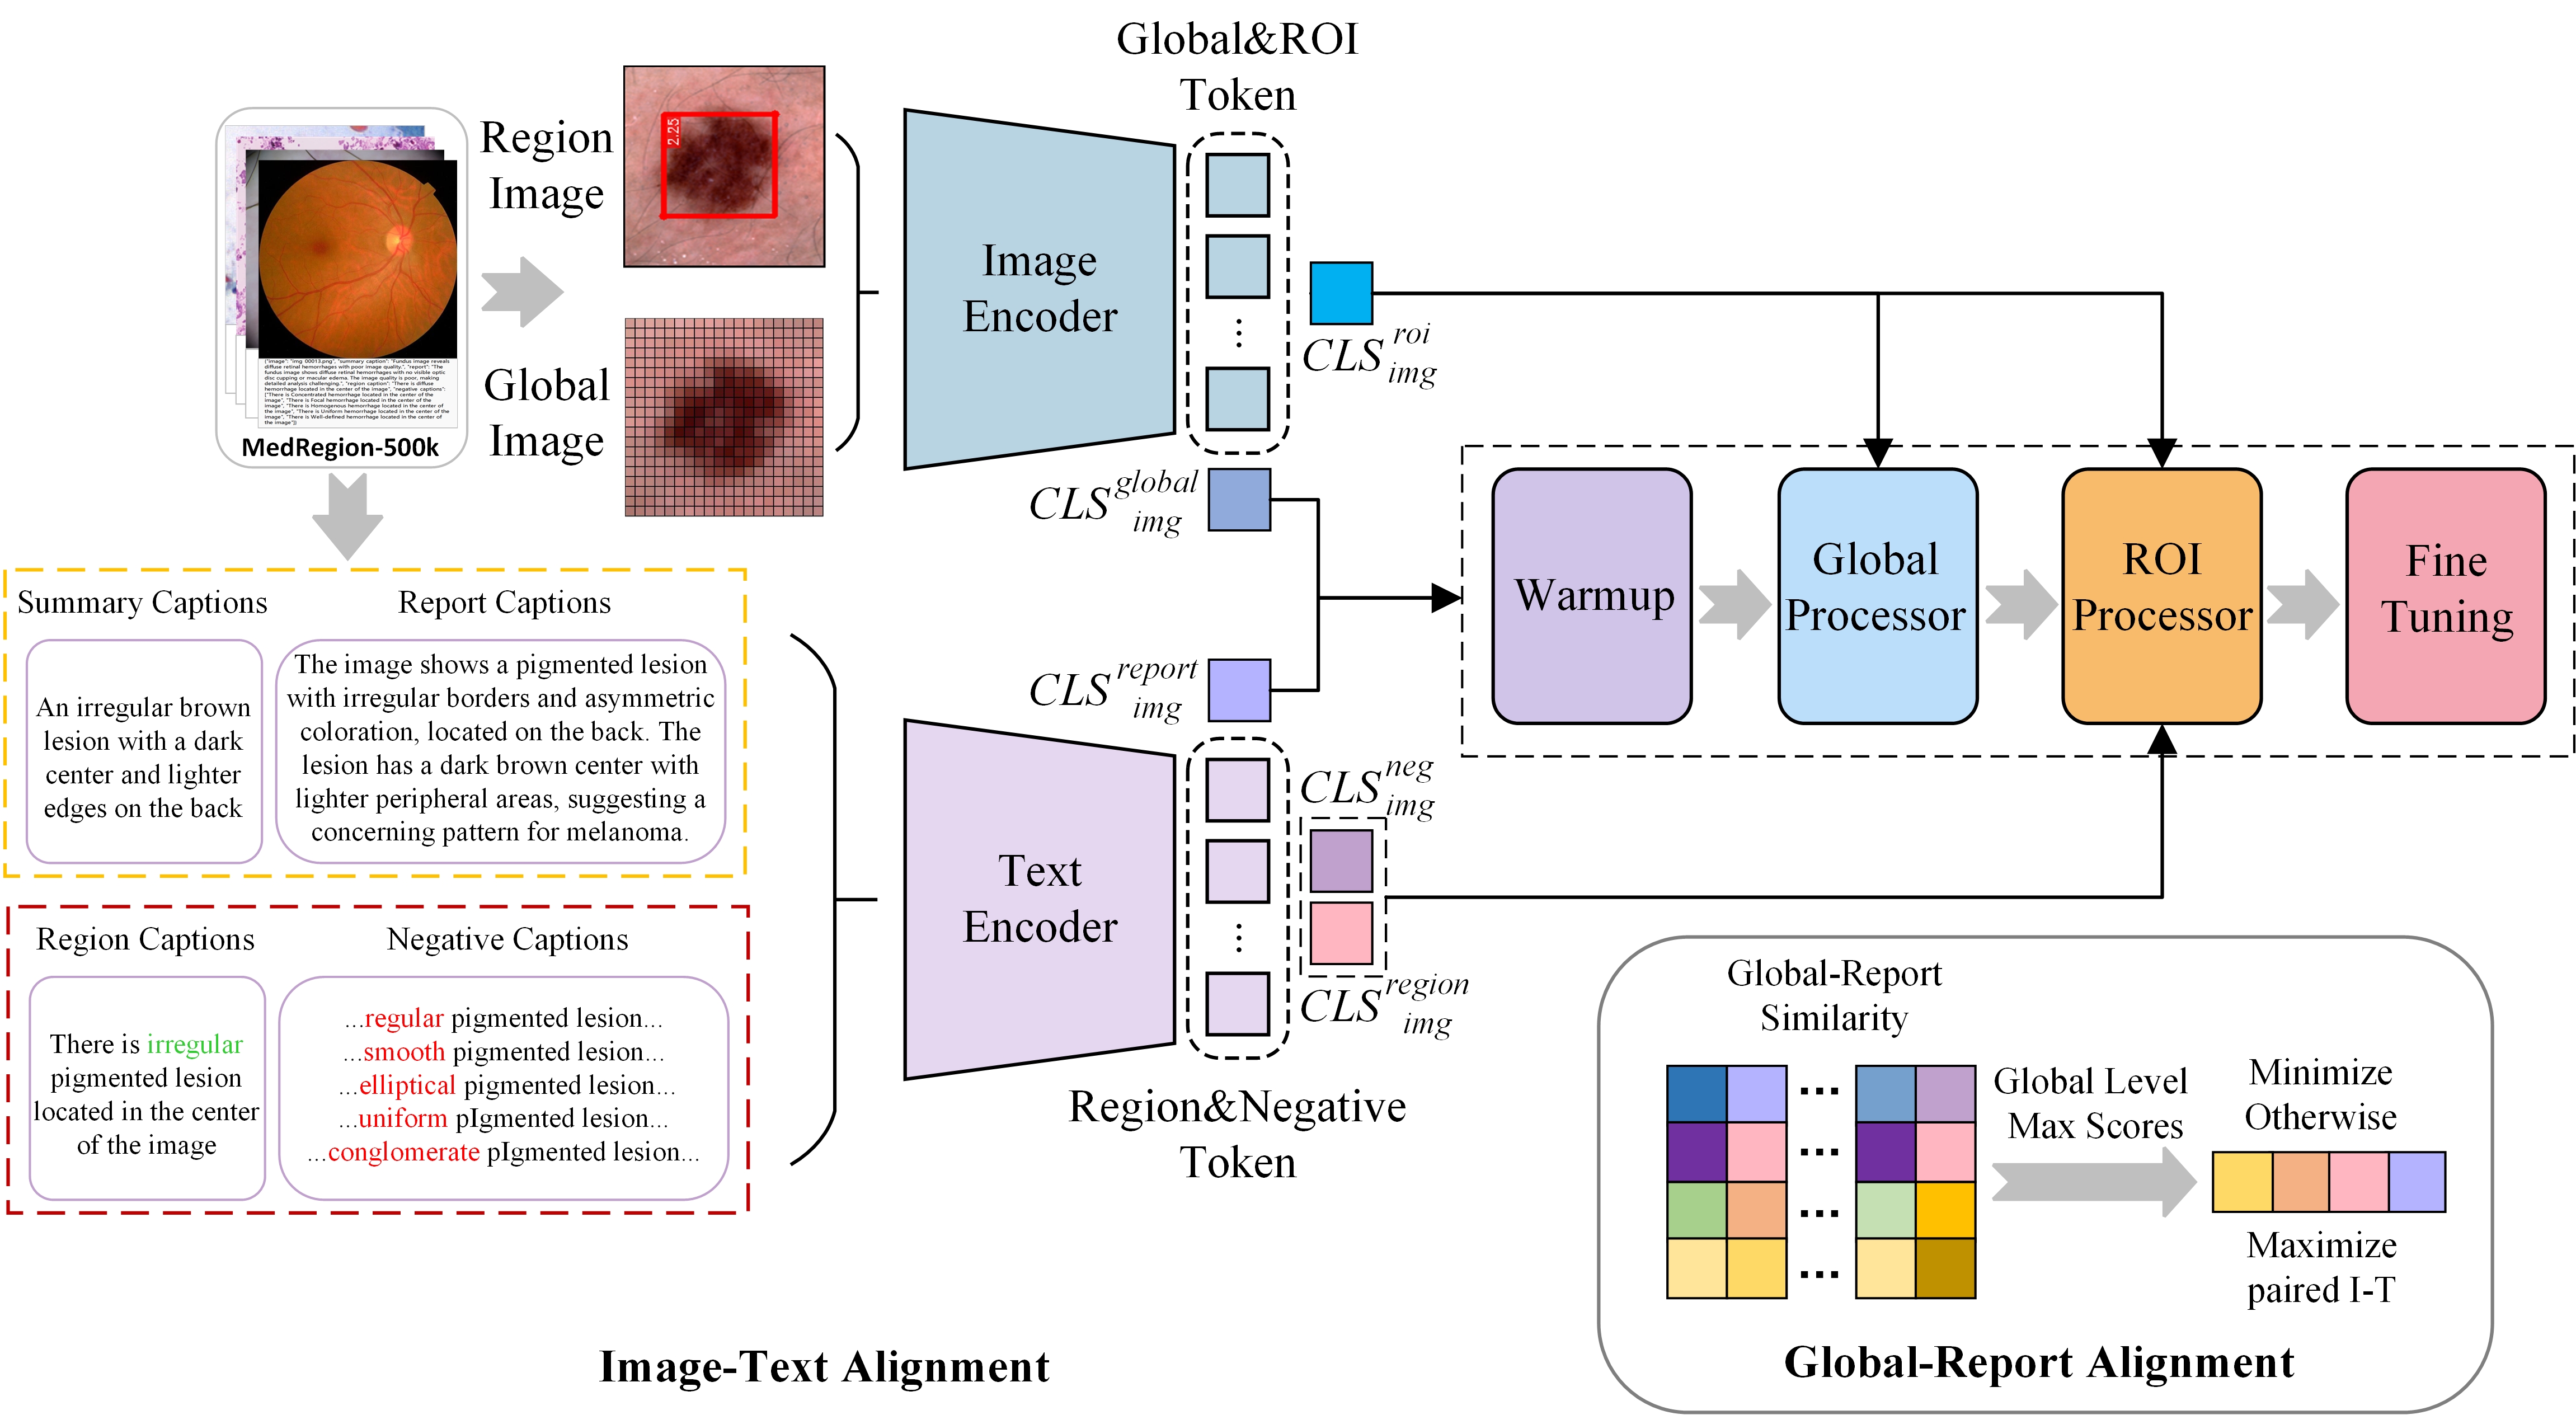
![Clip Multimodal Model [2508.05244] RegionMed-CLIP: A Region-Aware Multimodal Contrastive ...](https://ar5iv.labs.arxiv.org/html/2508.05244/assets/Fig3.jpg)
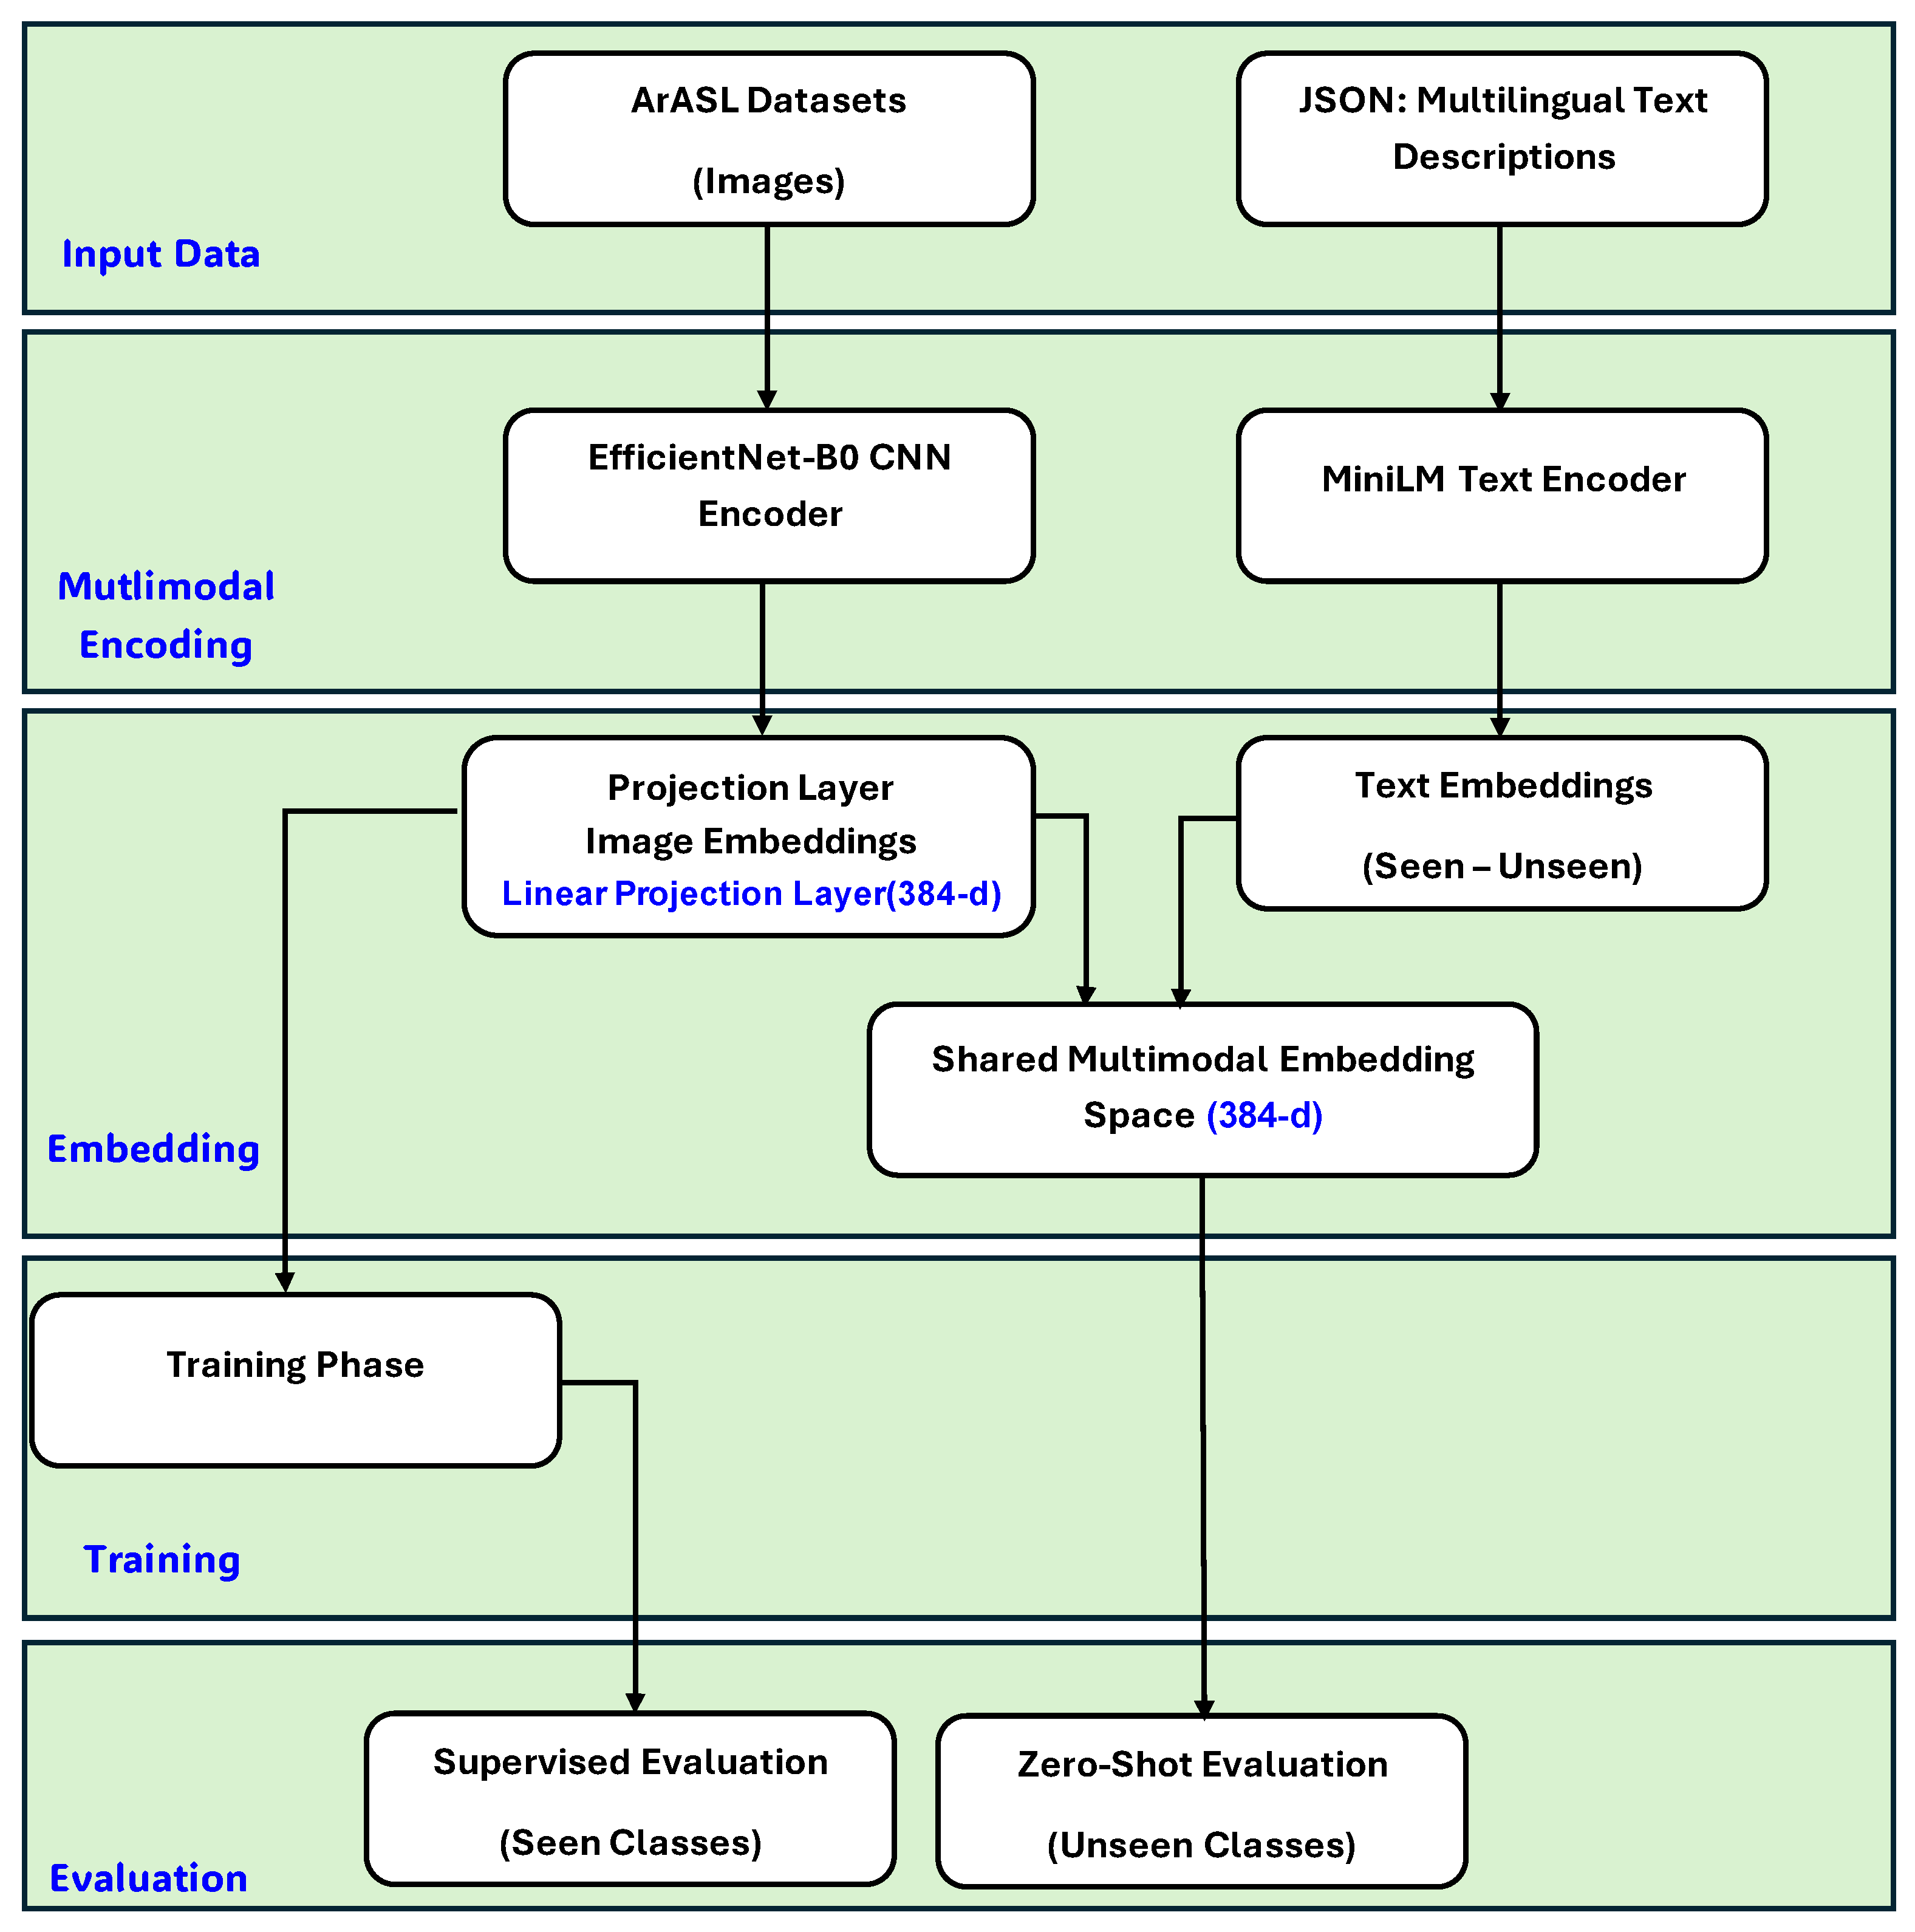
![Clip Multimodal Model [Revue de papier] jina-clip-v2: Multilingual Multimodal Embeddings for ...](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/jina-clip-v2-multilingual-multimodal-embeddings-for-text-and-images-1.png)

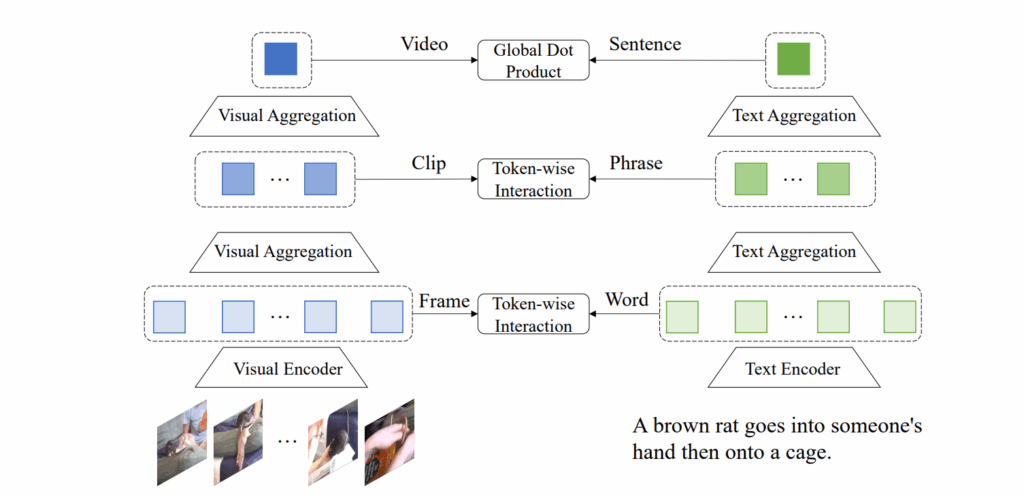
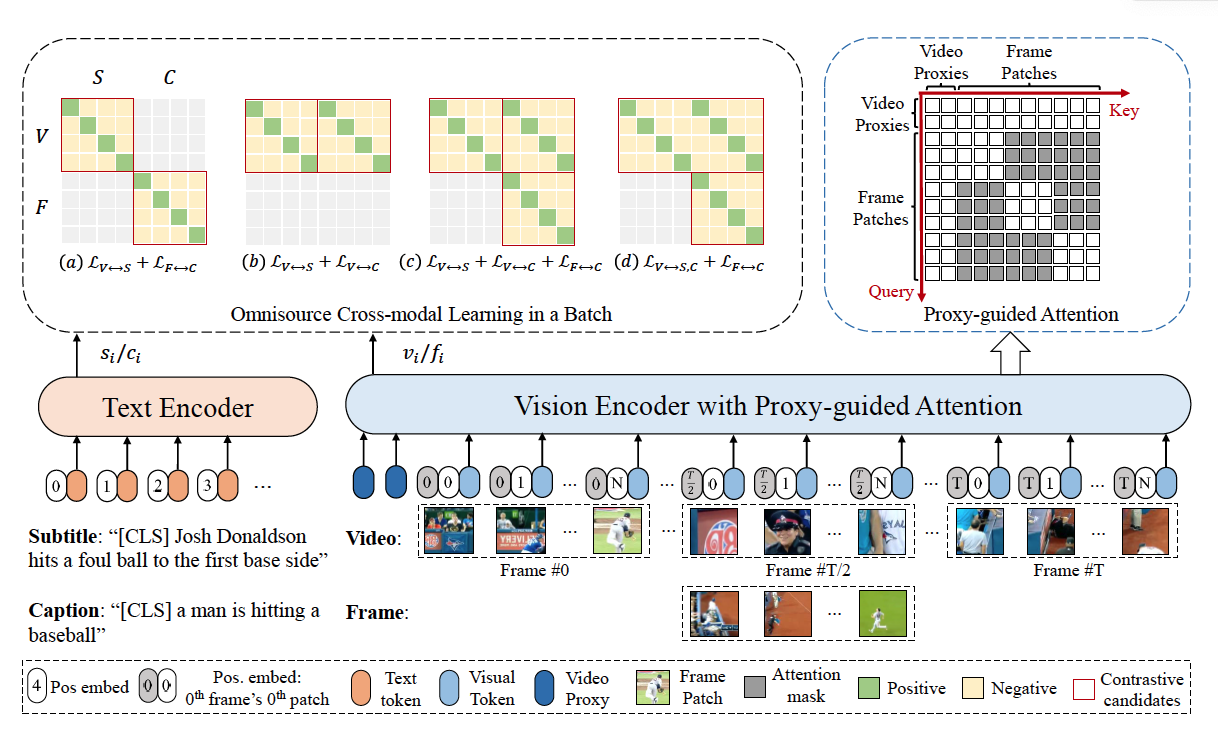
![Clip Multimodal Model [MultiModal] CLIP-ViP: Adapting Pre-trained Image-Text Model to Video ...](https://velog.velcdn.com/images/ji1kang/post/cad8b2c1-bbbb-451e-90a7-d8cfeef25eae/image.png)


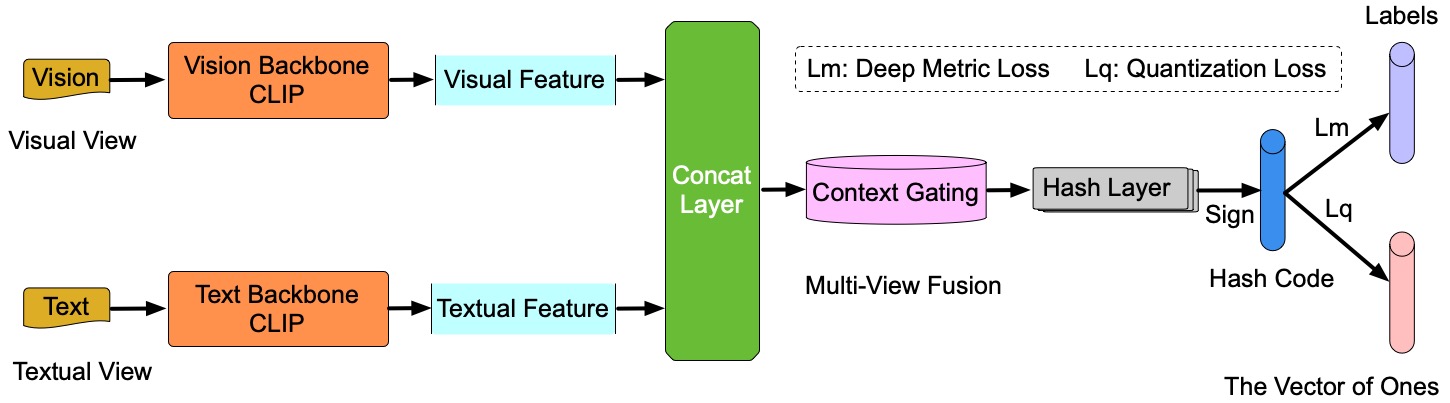
![Clip Multimodal Model [2308.11797] CLIP Multi-modal Hashing: A new baseline](https://ar5iv.labs.arxiv.org/html/2308.11797/assets/ARCH.jpg)


![Clip Multimodal Model [论文评述] Towards Effective and Efficient Long Video Understanding of ...](https://moonlight-paper-snapshot.s3.ap-northeast-2.amazonaws.com/arxiv/towards-effective-and-efficient-long-video-understanding-of-multimodal-large-language-models-via-one-shot-clip-retrieval-0.png)


![Clip Multimodal Model [2401.11649] M2-CLIP: A Multimodal, Multi-task Adapting Framework for ...](https://ar5iv.labs.arxiv.org/html/2401.11649/assets/figures/overview.png)